A Salesforce partner change touches more than a vendor name on an invoice. Production access, integrations, source code, sandboxes, deployment tooling, vendor accounts, documentation, and ongoing support all move at the same time, and each one can break quietly if the transition isn’t sequenced correctly. Most companies find this out mid-transition, when an integration user gets disabled before anyone confirms what depends on it, or when a repository turns out to be months behind what’s actually running in production.
This guide gives you a structured handover process instead of a general list of good intentions. It walks through what to prepare before notice is given, how to secure company-controlled access, what technical assets need a verified inventory, how to handle a transition mid-implementation, what the incoming partner should validate before taking on ownership, what the change typically costs, and what has to be true before you can call the Salesforce partner handover complete.
It’s written for the person coordinating the change, not just the developer inheriting the code. That usually means a platform owner, an IT or RevOps leader, or a program manager who has to answer for the transition’s outcome, whether or not they personally touch the org.
What a Salesforce Partner Transition Includes
A Salesforce partner transition is the controlled transfer of technical, operational, and project responsibility from one consulting team to another. It’s broader than changing who answers support tickets. Five areas move together:
- Salesforce org access. Administrator accounts, permission sets, and the identities tied to daily operation of the org.
- Technical assets and development. Source repositories, sandboxes, deployment tooling, and the code and configuration behind them.
- Integrations and credentials. Connected apps, named credentials, external credentials, and the API users that keep other systems talking to Salesforce.
- Project and business knowledge. Architecture decisions, process maps, and the reasoning behind configuration choices that aren’t visible in the metadata itself.
- Production support ownership. Who monitors the org, who responds to incidents, and who approves the next release.
A transition can happen after an implementation wraps, in the middle of an active project, during ongoing managed support, or as part of consolidating several vendors into one. The circumstances differ, but the same five areas need a verified owner in every case.
Partner selection matters, but it’s secondary to this question: what has to move, and who verifies that it moved correctly? That’s the actual job of a Salesforce consulting services engagement during a transition: confirm what needs to transfer and prove it transferred correctly, before anything else gets decided.
Should You Reset the Current Engagement or Change Salesforce Partners?
Not every frustration with a Salesforce partner means it’s time to switch Salesforce consulting partners. Some problems are fixed just as effectively by resetting expectations with the firm you already have.
| Situation | Practical response |
|---|---|
| Scope changed but delivery is still controlled | Rescope the engagement |
| Roles or governance are unclear | Reset responsibilities and acceptance criteria |
| Required expertise is missing | Add specialist support or assess another partner |
| Ownership cannot be established | Prepare a formal transition |
| Production or security risk exists | Begin controlled recovery and handover |
| Contract has ended | Plan an orderly transition |
Both planned and problem-driven transitions belong in this decision. Contract expiration, a shift toward different support needs, and internal staffing changes are planned reasons that have nothing to do with the current partner’s performance. Missing technical expertise, an acquisition, delayed work, poor documentation, and repeated production issues push toward a more deliberate change, sometimes through Salesforce remediation services rather than a full partner swap.
Treat this as a genuine decision point, not a formality on the way to a predetermined answer. A single missed deadline or one disagreement about scope isn’t, by itself, a reason to replace a consulting firm. Walking through the table above with your own leadership team, honestly, usually settles the question faster than another round of vendor meetings does.
How to Plan the Salesforce Partner Transition From Notice to Takeover
A transition goes better when it follows a defined sequence instead of running as a series of ad hoc requests to the outgoing team.
Phase 1: Prepare internally
Identify who owns the transition internally, gather current contracts, list active work, flag known risks, and set the dates the transition needs to hit.
Phase 2: Secure company access
Confirm administrative access and ownership of every external system before any accounts change. This has to happen before notice creates urgency around it.
Phase 3: Inventory technical assets
Review repositories, environments, integrations, packages, certificates, documentation, and deployment tooling against what’s actually running in production.
Phase 4: Transfer knowledge
Run structured technical and business handover sessions with the outgoing team while their knowledge of recent decisions is still fresh. This is also the natural point for an overlap period, where the outgoing and incoming partners work in parallel long enough for the new team to ask questions against a live system instead of a static document.
Phase 5: Incoming-partner validation
Have the new team independently verify the current state rather than accepting the outgoing team’s account of it. Overlap is only useful when the incoming partner uses it to check claims directly against the live org, instead of collecting a verbal summary and moving on.
Phase 6: Cutover and acceptance
Remove or reduce outgoing access, activate support ownership with the incoming team, and complete formal sign-off.
Access removal timing follows the technical dependencies uncovered during Phase 3, never a fixed calendar date. Plan the sequence this way and you sidestep the two failure modes that show up most often: cutting access too early and breaking a live connection, or leaving it open too long after ownership has already changed hands. It’s the kind of sequencing a Salesforce implementation consulting partner builds into the plan from day one.
VALiNTRY360 Salesforce Partner Transition Readiness Matrix
The following is a VALiNTRY360 editorial transition framework, built from the technical controls covered throughout this guide, not a published Salesforce survey or standard. Use it to score where your organization actually stands before the outgoing partner’s final day.
Score each area using one of four statuses: Verified, Needs update, Missing, or Unknown.
| Readiness area | What must be checked |
|---|---|
| Company access | Admin accounts and ownership confirmed under company control |
| Development assets | Repository, metadata, branches, and deployment path documented |
| System connections | Integrations, users, apps, credentials, and certificates inventoried |
| Data protection | Data backup and metadata recovery method confirmed |
| Documentation | Architecture, processes, runbooks, and decision history captured |
| Active work | Scope, defects, releases, backlog, and dependencies current |
| Third parties | Packages, vendors, licenses, and renewals accounted for |
| Production support | Incidents, monitoring, escalation, and ownership assigned |
An “Unknown” status is different from a “Missing” one. Missing means the business knows the gap exists. Unknown means nobody has checked yet, and that’s usually where the most expensive surprises come from during a transition.
In practice, the areas that come back “Unknown” most often are system connections and third parties. Integration users and connected apps tend to accumulate quietly over years, often set up by a developer who’s no longer on the account, and nobody owns the job of periodically re-verifying them. Documentation and active work are more likely to come back “Needs update” than fully missing, since some record usually exists, just not one that matches what’s actually running today.
Run this matrix before finalizing the transition timeline, never during the final week. Scoring an area “Unknown” isn’t a failure of the exercise. It’s the exercise working, because it tells you exactly where the incoming partner needs to spend discovery time before making any commitments. Walk into an engagement with a completed matrix already in hand, and the first weeks look completely different: less time spent discovering what you inherited, more time spent actually stabilizing and improving it. That’s the difference a Salesforce managed support services team notices immediately.
Secure Salesforce Access and Company Ownership Before Handover
Access is the first control to lock down, and it needs its own sequence rather than a single “remove the old team” step.
- Verify company-controlled System Administrator access.
- Inventory outgoing consultant users.
- Review permission sets and elevated access.
- Identify integration users.
- Review connected apps.
- Identify active OAuth access.
- Review external credentials and named credentials.
- Check repository and deployment-platform accounts.
- Identify shared accounts that need replacement.
- Create an access-removal sequence.
Some of these accounts can’t be disabled the moment notice is given. A named credential or connected app tied to an outgoing consultant’s identity may still be authenticating a live integration, and revoking it without a replacement in place stops that connection cold. Refresh tokens tied to a connected app’s OAuth policy can also remain usable until they’re explicitly revoked, so “the contract ended” isn’t the same as “the access is gone.” An admin can revoke a token directly from a user’s detail page or from the OAuth Connected Apps Usage page in Setup, but that step should come after the dependency is understood, not before.
Named users deserve the same discipline. A departing consultant’s individual login is easy to deactivate, but a shared or generic admin account used across the whole engagement is harder to retire cleanly, since disabling it can silently break whatever automation or integration was quietly authenticating through it. Flag every shared account explicitly during the inventory step rather than assuming it belongs to one person.
The correct order is to identify dependencies first, establish replacement ownership for each one, test the affected process with the new ownership in place, and only then perform the agreed access cutover. Skipping straight to cutover is the fastest way to turn a routine transition into an incident.
Audit Integrations, Credentials, Certificates, and Installed Packages
This is where partner transitions most often lose track of something. Build a register that captures each asset alongside its business purpose, authentication method, owner, dependencies, and the action required before cutover.
| Asset | Business purpose | Authentication | Owner | Dependency | Action required |
|---|---|---|---|---|---|
| Billing integration | Sync invoices to Salesforce | Named credential | Finance systems owner | Nightly batch job | Confirm new owner, rotate credential |
| SSO connected app | Employee login to Salesforce | Certificate-based | IT security | Company-wide authentication | Verify certificate ownership before any change |
| Marketing platform sync | Push leads into Salesforce | OAuth connected app | RevOps | Lead-routing automation | Test after ownership transfer |
Integrations
Cover every connected system: ERP, billing, marketing, support, identity, middleware, data platforms, and custom APIs. Each one needs a documented business purpose, direction, and owner, beyond a name sitting in a setup menu. Before anyone proposes changing a single one of these connections, a Salesforce integration services partner should already have every one of them mapped.
Credentials
Integration users, named credentials, external credentials, secrets, and API access all need a confirmed owner. Salesforce’s external credentials guidance ties access to profiles or permission sets and recommends limiting each principal to the access level its work actually requires, which is a useful standard to re-apply during a transition rather than just carrying forward whatever access already exists.
Certificates
Record each certificate’s purpose, expiration date, SSO use, callout dependency, and the person or team responsible for renewal. Deleting a certificate that’s still tied to single sign-on or an Apex callout can break authentication without warning, so dependencies need confirmation before any certificate is touched.
Installed packages
Capture publisher, version, licensing, primary contact, support contact, dependencies, and renewal information for every installed package. Salesforce lets an admin become the primary contact on a package when the current contact needs to change, which matters here specifically: an outgoing consultant can otherwise stay the operational contact for software the client still depends on.
Removing a certificate or credential before its dependency is identified is the single most common way a transition causes an outage that had nothing to do with the actual handover plan.
Reconcile Source Control, Sandboxes, and the Deployment Process
Possessing a repository doesn’t prove it matches what’s running in production. That has to be verified directly.
Work through this sequence: production, metadata comparison, source repository, branches, sandboxes, deployment tooling, release approval.
The incoming team should be able to answer:
- Which repository is authoritative
- Which branch represents production
- Whether production contains changes missing from source control
- What’s in each currently open branch
- Each sandbox’s purpose and current status
- The current deployment method
- Which automated tests actually run
- Who approves a production release
- Whether a documented rollback process exists
- Who owns the CI/CD pipeline
- Whether configuration drift is being tracked
Salesforce’s own Operational Excellence guidance treats source-driven development, version-controlled metadata, CI/CD, and scheduled drift detection as standard practice, not optional extras, which makes it a reasonable bar for judging what you’re inheriting. That guidance also recommends comparing production configuration against source control on a regular cadence, so ask the outgoing team when drift was last checked, not just whether a repository exists.
For sandboxes specifically, source tracking is only available in Developer and Developer Pro sandboxes, so a Partial Copy or Full sandbox won’t show the same change history and needs a different verification approach. A refresh also resets the sandbox’s org ID and, depending on type, pulls in fresh metadata or fresh metadata plus data from production, so a sandbox that hasn’t been refreshed in months may no longer resemble the org it’s supposed to represent.
Record each sandbox’s name, type, last refresh date, current active work, and role in the deployment path directly in the handover documentation, because a sandbox labeled “UAT” can just as easily be carrying stale metadata or someone else’s active development. This reconciliation has to happen before anyone commits to anything about the codebase. That’s exactly how a Salesforce development services team should treat it: as a precondition, never an afterthought.
Protect Salesforce Data, Metadata, and Audit Evidence Before Cutover
Three separate things need protection before major transition changes begin, and they don’t all use the same recovery method.
Data protection
Confirm the current backup method for records, files, and business information, and confirm who’s responsible for recovery if something goes wrong during the transition itself.
Metadata protection
Objects, fields, automation, permissions, layouts, and Apex configuration need their own protection separate from data. Source-controlled metadata is the strongest version of this; without it, a transition has no reliable way to reconstruct configuration if something breaks mid-handover. A recent metadata export, even outside a full CI/CD pipeline, is far better than nothing, since it gives the incoming team a known-good state to compare against if something is missing or misconfigured after cutover.
Audit evidence
Capture relevant Setup Audit Trail history while the outgoing team’s recent activity is still identifiable. The Setup Audit Trail page itself displays the 20 most recent setup changes on screen, but authorized users can download the org’s complete setup history for the past 180 days, which is the more useful export to pull before the transition closes out and that history starts aging past the retention window.
Schedule a pre-cutover backup deliberately, before any major access, deployment, or configuration change the transition plan calls for. Leaving it to whatever the last routine backup happened to catch is how gaps go unnoticed. Salesforce’s own backup guidance and its Setup Audit Trail documentation both treat this as standard practice, worth doing on every org regardless of a transition. Data protection and metadata protection tend to get evaluated together anyway, which makes a Salesforce data governance services review a natural place to fold this step into.
Build a Salesforce Knowledge-Transfer Package the New Partner Can Use
A meeting is weak handover evidence on its own. It needs to produce artifacts the incoming partner can reference after the outgoing team is gone.
None of this has to be built from scratch. Most of it already exists somewhere, in a project plan, a support ticket, an old diagram drawn for a different purpose, and the job during a transition is to collect it into one place rather than generate it fresh. The four categories below group what typically gets lost first, not because a formal deliverable requires it, but because it’s the material a departing team carries in their heads and rarely writes down unless someone specifically asks.
Architecture
- Current architecture diagram
- Data model notes
- Automation inventory
- System-connection map
- Security model
Delivery
- Repository guide
- Environment map
- Release procedure
- Test process
- Deployment runbook
Operations
- Known incidents
- Support process
- Monitoring setup
- Vendor list
- Renewal calendar
Business context
- Business-process maps
- Reporting dependencies
- Roadmap
- Technical-debt register
- Decision history
Assign each artifact an owner and one of the four readiness statuses from the matrix above. Recording a document as “Missing” is more useful to the incoming team than pretending it exists. An honest gap list gives a Salesforce managed services partner something real to plan around. An optimistic status report just delays the discovery, usually until production. Tie the deadline for this package to the outgoing team’s last active day, because verbal knowledge gets much harder to recover once the people who held it are gone.
How to Transition Salesforce Partners During an Active Implementation
A transition that happens mid-project needs its own baseline, established from evidence rather than from whatever completion percentage shows up in a status report.
| Area | What the incoming partner verifies |
|---|---|
| Contracted scope | What was originally committed |
| Requirements | What the business still needs |
| Configuration | What currently exists |
| Code | What has been built |
| Testing | What has passed |
| UAT | What users have accepted |
| Deployment | What has reached production |
| Defects | What remains open |
| Dependencies | What is blocking delivery |
| Backlog | What still has business priority |
| Commercial status | What has been accepted or disputed |
A reported completion percentage can quietly combine finished work, partially tested work, requirements nobody has revisited in months, and items that no longer matter to the business at all. None of that shows up in a single number.
Establishing this baseline usually takes longer than either side expects going in, sometimes a full week or more on a complex build, and that time is worth protecting in the transition timeline rather than compressing it to hit an arbitrary go-live date. Rushing this step is how a new partner ends up recommitting to a delivery date built on the same unverified assumptions that caused the original transition.
The incoming partner’s job is to rebuild the baseline from what’s verifiably true today. Every new delivery commitment gets built on that baseline, never the prior estimate. Salesforce implementation services and Salesforce remediation services work overlap most right here: stabilizing a half-finished build and continuing it forward are often the same engagement. Stakeholders should expect a revised estimate once the baseline exercise wraps, and even a later date is more trustworthy than a number nobody has re-checked.
How to Choose the Incoming Salesforce Partner for a Takeover
Selecting a replacement partner is its own piece of due diligence, and a takeover project needs different evidence than a greenfield implementation does. Ask the firm you’re evaluating to show:
- Relevant Salesforce products
- Similar takeover or remediation work
- Named team members
- Current-state assessment process
- Source-control review method
- Integration experience
- Security review capability
- Documentation process
- Support model
- First-release plan
The right scope depends on what’s actually broken. A full consulting engagement makes sense when governance, architecture, and delivery process all need rebuilding at once. When the gap is narrower, a specific integration, a stalled release, a security review, it can make more sense to hire a Salesforce consultant directly rather than re-staffing an entire program. Match the engagement size to the actual scope of what needs fixing, not to whatever model the outgoing partner used.
Use Salesforce Partner Finder alongside current partner-program information to verify public credentials before you rely on them; its underlying data refreshes on a 1-to-2-week cycle, so it’s close to current but not necessarily same-day accurate. Treat what you find there as a starting point for verification, not a substitute for it. Confirm active certifications and named specializations directly with the firm, since a public profile can lag behind staff changes that happened in just the last few weeks.
A large certification count is weak evidence on its own for a takeover project. What matters more is the named delivery team you’ll actually work with and a concrete method for understanding an inherited org, rather than building one from scratch. VALiNTRY360’s own takeover engagements start with the readiness matrix above precisely because it forces that method into the open before any commitments get made. Ask specifically who on the team will be doing the discovery work, not just who signs the statement of work, since the two aren’t always the same people.
What Does a Salesforce Partner Transition Cost?
There’s no dependable public price for changing Salesforce consulting partners, and any number presented as universal should be treated with suspicion. What’s worth discussing instead is what drives the cost up or down.
| Cost area | What may create work |
|---|---|
| Current-state assessment | Org and architecture review |
| Knowledge-transfer overlap | Time from both consulting teams |
| Access transition | Accounts, credentials, and security work |
| Source reconciliation | Missing or stale repository content |
| Integration investigation | Undocumented system dependencies |
| Regression testing | Verification before new releases |
| Documentation reconstruction | Missing technical and business records |
| Production repair | Existing defects or unstable processes |
| Backlog reset | Requirements and priority review |
| Support onboarding | Monitoring, incidents, and escalation setup |
Current documentation, controlled source, clearly defined owners, known system connections, and a well-understood project state all make a transition faster and cheaper to execute. Each gap in that list adds discovery work before the incoming partner can commit to anything with confidence.
Ask any firm quoting a transition for a cost breakdown by phase, current-state assessment, stabilization, and ongoing support, rather than a single bundled number. A bundled figure makes it hard to tell whether you’re paying for genuine discovery work or for time spent repeating assessments a previous vendor should have already documented. A phased quote also gives you a natural checkpoint to pause after the assessment if the findings change your plans.
The Incoming Partner’s First 30 Days and Transition Sign-Off
The first 30 days set the tone for the entire relationship, and they work best as three distinct stages rather than one long onboarding period.
First stage: validate
The incoming team verifies access, architecture, source, integrations, open incidents, deployment process, and active projects against what was documented during handover. Where the documentation and the live org disagree, the live org wins, and the discrepancy gets logged rather than quietly overwritten. This stage typically surfaces a handful of small surprises, an environment variable nobody flagged, a workflow rule that behaves differently than described, and catching them now costs far less than catching them during the first real release.
Second stage: stabilize
Address anything that can affect production, security, deployment, or business continuity before taking on new commitments.
Third stage: assume ownership
The incoming team formally takes responsibility for support, releases, backlog governance, and the Salesforce work agreed to in the transition plan.
Transition acceptance checklist
Sign off only after verifying:
- Company-controlled administrative access
- Incoming access approved
- Outgoing access handled according to the cutover plan
- Connected-app access reviewed
- Integration ownership documented
- Source reconciled with production
- Deployment route verified
- Sandboxes documented
- Backup approach confirmed
- Package and vendor contacts transferred
- Incidents assigned
- Backlog re-baselined
- Required documentation accepted
- Support escalation active
- First operational task or controlled release completed
That last item matters more than it looks. A transition that’s “complete” on paper but hasn’t yet survived a real release or a real incident hasn’t actually been tested. The real proof is the first successful release under new ownership, not the signed handover document, and that’s the bar a Salesforce managed support services team should hold itself to.
Related VALiNTRY360 Salesforce Case Studies
Every principle in this checklist plays out in real engagements, most of them takeovers, migrations, or fixes to a system a previous team left behind. If you want to see how that works in practice, here are five VALiNTRY360 case studies worth a look.
1. Real California Milk: From Manual Reconciliation to a Single Source of Truth
Real California Milk was running constituent and partner relationships on SugarCRM, with data arriving in batches that required manual reconciliation before anyone could trust a report. VALiNTRY360 migrated Accounts and Contacts into Salesforce Sales Cloud, built an ETL tool with custom automations for the quarterly import cycle, and connected MailChimp and Zoom so activity tracking stayed in one place instead of scattered across systems.
Key takeaway: Annual labor spent manually updating data fell from 500 hours to 4, and Salesforce became the organization’s single source of truth, the same standard a partner transition should hold any inherited system to.
Read the full case study: Real California Milk: SugarCRM to Salesforce Migration
2. AthenaPsych: Replacing an EMR Without Losing Clinical Continuity
AthenaPsych, a New York State mental health provider, had outgrown its existing EMR and needed a platform that could scale intake and care delivery without sacrificing accuracy. VALiNTRY360 built a replacement on Salesforce Health Cloud, adding Scheduler, Shield, and Experience Cloud alongside integrations with Change Healthcare and Vonage, then handed off a system the clinical team could run day to day.
Key takeaway: Within six months, 80% of patients were scheduled on the first call, CPT coding errors dropped 69%, and clinical compliance errors dropped 75%, evidence that a well-documented replacement can outperform the system it replaced almost immediately.
Read the full case study: AthenaPsych Salesforce Health Cloud EMR Replacement
3. Ravago: Taking Over and Rebuilding an Underused Marketing Cloud Instance
Ravago’s existing Marketing Cloud instance had been built for its core B2B distribution business and couldn’t segment or message the direct-to-consumer audience the company wanted to reach. Rather than starting over, VALiNTRY360 reengineered the data architecture and automations inside the existing instance, redesigned the customer journeys, and added a loyalty program and SMS channel on top of what was already there.
Key takeaway: The rebuilt instance generated $500,000 in new revenue within three months, a reminder that a takeover engagement is often about making an inherited system do a job it was never built for, not replacing it outright.
Read the full case study: Ravago Salesforce Marketing Cloud Optimization
4. BIC Graphic: Unifying Fragmented Ownership Across Sales, Marketing, and Service
BIC Graphic had no CRM at all, and sales, marketing, and service teams each kept their own version of what had happened with a customer, exactly the kind of fragmented ownership a partner transition has to untangle. VALiNTRY360 implemented Sales Cloud and Service Cloud together, integrated the existing ERP, and automated the workflows connecting field sales, inside sales, and quoting into one record per customer.
Key takeaway: Average handle time dropped by seven minutes and new pipeline opportunities increased more than 27%, results that came from consolidating ownership, not from adding new tools.
Read the full case study: BIC Graphic Salesforce Sales Cloud and Service Cloud Implementation
5. AdventHealth University: Migrating 25 Years of Records Into One Usable System
AdventHealth University had 25 years of alumni records spread across disconnected systems that four separate departments relied on without being able to act on the data. VALiNTRY360 ran a full ETL migration into a single Salesforce org, configured Opportunity Management for fundraising, and connected daily workflows through Outlook so the university finally had one record per alumnus instead of four partial ones.
Key takeaway: A quarter-century of legacy data moved into a working system without losing history, the same bar a knowledge-transfer package should clear during any partner handover.
Read the full case study: AdventHealth University Salesforce Implementation
Frequently Asked Questions
1. What is a Salesforce partner transition?
It’s the controlled transfer of Salesforce access, technical assets, integrations, project knowledge, and support ownership from one consulting partner to another.
2. When should a company change its Salesforce partner?
When ownership, delivery, or expertise gaps can’t be resolved by resetting the current engagement, or when a planned event like contract expiration or vendor consolidation makes a change the more sensible option.
3. Can you change Salesforce partners during an active implementation?
Yes. The incoming partner needs to rebuild the project baseline from verified evidence rather than accepting a reported completion percentage at face value.
4. What should you collect before your current Salesforce partner leaves?
Company-controlled access, a technical asset inventory, source and deployment documentation, integration and credential details, and a completed knowledge-transfer package.
5. Who should own Salesforce administrator access during a partner transition?
The client company, verified and confirmed before the transition begins, not assumed based on who originally set up the org.
6. How do you transfer Salesforce source code and deployment ownership?
Confirm which repository and branch represent production, reconcile any gaps against the live org, and document the deployment path, testing, and release approval process.
7. How should integration accounts and credentials be handled during handover?
Inventory every integration user, connected app, and credential, confirm its owner and dependency, and replace ownership before revoking any access.
8. When should the outgoing partner’s Salesforce access be removed?
After dependencies are identified and replacement ownership is tested, not automatically on the day the contract ends.
9. What should you do when Salesforce documentation is incomplete?
Record it as missing rather than guessing, and treat reconstruction as part of the transition scope instead of a surprise the incoming partner absorbs later.
10. Should the outgoing and incoming Salesforce partners overlap?
An overlap period earns its cost when the incoming partner uses it to test claims against the live org directly, rather than receiving a walkthrough from the outgoing team and taking it at face value.
11. What should a new Salesforce partner review first?
Company access, source-to-production reconciliation, and active integrations, since those three areas carry the most risk if something is wrong.
12. How long does a Salesforce partner transition take?
It depends on documentation quality, system complexity, and how many gaps the readiness matrix turns up, so a fixed timeline shouldn’t be assumed before that assessment happens.
13. What affects the cost of changing Salesforce partners?
Documentation quality, source-control accuracy, integration complexity, and the state of the active project or backlog all directly affect how much discovery work the transition requires.
14. How do you verify a replacement Salesforce consulting partner?
Check relevant product and industry experience, named team members, and their process for assessing an inherited org, using Salesforce Partner Finder and direct reference conversations.
15. How do you know a Salesforce partner transition is complete?
When access, source, integrations, backups, documentation, and support ownership are all verified, and the incoming team has completed a real release or operational task successfully.
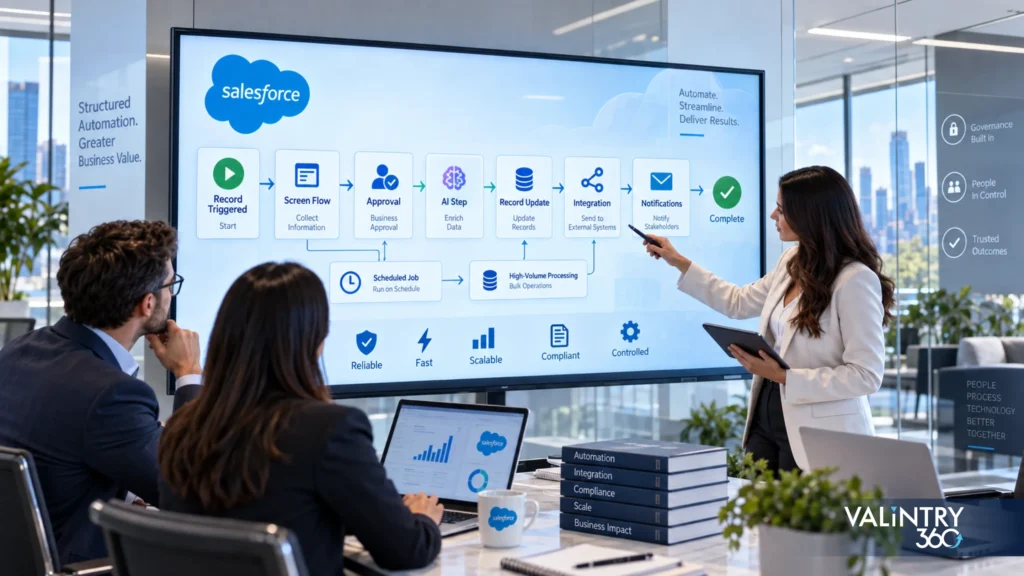
The choice comes down to how much of the execution path you can specify before the process runs. Most production architectures end up using both tools, with each one owning the part of the process it suits.
- Salesforce Flow owns defined execution. Where every branch, condition and action can be configured ahead of time, Flow gives you a path you can test, replay and audit.
- Agentforce owns contextual reasoning. Where the goal is clear but the route depends on user intent, retrieved data or conversation history, an agent decides which permitted action fits.
- Hybrid architecture handles most real processes. Agents can call Flows, Flows can call agents, and Flow can run a single bounded AI step without handing over the whole process.
- Volume, latency, testing and cost decide the edge cases. High-throughput synchronous work favors Flow. Metered agent actions, behavioral testing and reasoning traces all change what the design costs to run and govern.
What Is Salesforce Flow, and Where Does It Fit?
Salesforce Flow is the platform’s configured automation layer. You define what starts a process, which conditions select each branch, which actions run, and what happens at each outcome, all before anything executes.
Salesforce documents a wide set of flow types, including record-triggered flows in after-save, before-save and before-delete variants, schedule-triggered flows, screen flows, autolaunched flows, platform event-triggered flows, and external system change-triggered flows. Approvals get their own types too, with an Autolaunched Flow Approval Process and a Record-Triggered After Save Flow Approval Process, which matters because approval sequence is one of the strongest arguments for keeping a process in Flow.
Data 360 work runs through activation-triggered, segment and campaign flows, plus a Data Cloud Data Change Flow that launches when a Data 360 data model object or calculated insight changes and meets set conditions.
A typical path looks like this:
Record created → conditions evaluated → fields updated → routed for approval → owner notified
Every step in that sequence was decided at design time. That’s the property that makes Flow testable against expected outcomes and replayable when someone asks why a record changed.
One correction worth making early, because it shapes the cost conversation later. Flow Builder ships with Essentials, Pro Suite, Professional, Enterprise, Performance, Unlimited and Developer editions, but several connected capabilities carry their own requirements. Apex actions need an Apex license, Data 360 features need Data 360 users, Einstein generative AI needs the Einstein for Sales, Einstein for Service or Einstein Platform add-on, and MuleSoft RPA needs a MuleSoft Automation subscription.
For the wider 3-tool picture including where code belongs, the VALiNTRY360 Agentforce, Flow and Apex comparison covers that ground separately. Salesforce’s flow types reference lists the current set in full.
What Is Agentforce, and How Does Its Execution Model Differ?
Agentforce takes a request, interprets what’s being asked, and works toward the goal using actions you’ve granted it. Within an active subagent, the agent reads context, chooses an action, runs it, reads the result, and decides what comes next. (Salesforce renamed topics to subagents in April 2026, so older documentation describes the same mechanism under the previous name.)
Salesforce describes Agent Builder as connecting “to your data, channels, and existing Salesforce assets like Flows, Apex, MuleSoft APIs, and prompt templates.” Those connected assets become the actions the agent selects among.
Grounding is a separate question from actions. An agent reading Salesforce records and calling Flows needs no extra data platform, while Agentforce Data Library requires Data 360 because its index and retriever are built there. That distinction decides whether Data 360 enters your architecture at all.
The runtime shape differs from Flow in one specific way:
User request → agent interprets intent → selects a permitted action → Flow, Apex or API executes → result returns → agent decides the next step
The goal is fixed. The route through it depends on what the person asked and what the agent finds along the way. That variability is the feature, and it’s also the property that changes how you test, audit and budget for the process.
How the agent picks matters for design. The reasoning engine works from action names, descriptions, input and output definitions, and the active subagent’s instructions. Vague action descriptions produce vague selection, which is why agent quality often comes down to how precisely each action was described.
Scope does real work too. A subagent narrows the actions in play for a kind of request, reducing both wrong selections and the number of actions burned reaching an answer.
Our guide to how Agentforce works covers the reasoning loop in more depth, and Salesforce’s Agent Builder page documents the current build surface.
Agentforce vs Salesforce Flow at a Glance
Decision area | Salesforce Flow | Agentforce |
|---|---|---|
Execution model | Configured path | Runtime reasoning |
Input | Structured data or system event | Conversational or contextual |
Trigger | Record, schedule, event, screen, API | User interaction or context |
Path predictability | High | Varies by request |
Multi-turn conversation | Limited | Designed for it |
Business rules | Configured explicitly | Instructions plus permitted actions |
High-volume transactions | Strong fit | Assess latency and cost first |
Fixed action order | Strong fit | Use Flow, Apex or Agent Script for control |
External systems | Configured integration path | Runtime choice among permitted actions |
Testing | Path and assertion testing | Behavioral and action evaluation |
Audit evidence | Flow Trigger Explorer and debug output | Reasoning and action traces |
AI requirement | Optional | Central |
Consumption model | Edition and add-on licensing | Metered usage or agent licensing |
Best fit | A defined process | A contextual goal |
Read that table as a guide to the dominant execution model rather than a verdict. Most Salesforce Flow vs Agentforce debates get settled by 3 rows rather than 14, and plenty of production processes contain both kinds of work anyway.
Fixed action order is the row underestimated most, because natural-language instructions can suggest a sequence without guaranteeing it. Volume sets a ceiling no design work removes.
Audit evidence is usually decided in compliance, outside the architecture conversation, so ask early. Existing Salesforce Flow automation already clears that bar, which is part of why replacing it needs a real reason.
The remaining rows shift with the process. A conversational interface points toward an agent, but only if the actions behind it justify the reasoning step.
The Main Decision: How Predictable Is the Execution Path?
Salesforce’s architecture decision guide organizes this choice under a framework it calls Orchestration Density, measured across 3 dimensions: how specifically the execution path can be defined at design time, how much the goal’s outcomes vary, and what mix of input and output modalities the process handles.
That framing is more useful than a 2-way split, because it tells you where a process sits rather than which product wins.
Fully specified path
Choose Flow when every meaningful branch can be defined before runtime. Updating a record, applying routing criteria, requesting an approval, sending a notification, running a fixed calculation. You know the trigger, the conditions and the outcome in advance.
A useful test: if you can draw the process with every branch labeled, and the room agrees on what happens in each edge case, it’s a Flow.
Context-dependent path
Agentforce becomes relevant when the right next action depends on what the user means, what the conversation has covered, what was retrieved, what an earlier action returned, or what information is still missing.
That test fails here in a specific way. You can draw the goal and the available actions, but the arrows between them depend on the request, so the diagram becomes a set of options rather than a path.
Mixed path
Most substantial processes land here. Some steps need interpretation and others need transaction integrity, which is what Salesforce calls hybrid orchestration, and the 4 patterns for building it come later in this article.
Claims handling is the standard example. Classifying an unstructured description needs reasoning, while checking policy limits and writing the record needs a guaranteed sequence. Splitting the process along that seam usually costs less than routing every step through an agent.
The full spectrum runs:
Fixed rules → Flow with a bounded AI step → Flow calling Agentforce → Agentforce calling Flow or Apex → Agentforce with controlled agent logic
Placing a process on that line is the architecture decision itself, and it’s the question a Salesforce consulting review works through before any build starts. Salesforce’s decision guide sets out the full framework.
When Salesforce Flow Is the Better Fit
Record automation. Field updates, task creation, ownership changes and notifications where the trigger and the result are both known. Flow executes these in milliseconds inside the platform transaction.
Approval and compliance paths. Processes where the sequence is the control. An approval that must happen before a status change belongs in configured automation, where the order is guaranteed rather than inferred.
Scheduled and event-driven work. Recurring jobs, platform events and system-triggered automation. No interpretation is involved and the same logic runs every time, which is exactly the shape configured automation handles best.
High-volume transactions. Salesforce is direct about this one: “Agentforce is unsuitable for high-volume, synchronous record processing where latency is a primary constraint.” If thousands of records need the same treatment quickly, configured automation is the answer.
Guided user processes. Screen flows that walk someone through a defined set of steps, collecting structured input along the way. The person supplies the judgment and the Flow supplies the structure.
Fixed integration logic. Where Salesforce always calls the same external service under the same conditions, the integration path can be configured rather than chosen at runtime. Known target, known payload, known failure handling.
Anything already working. An existing Flow carrying correct business logic starts from a position of evidence, and a later section covers when that’s worth changing.
A Flow can still use AI at a single bounded step without an agent taking over the process. A prompt template that summarizes a case inside an otherwise fixed Flow keeps orchestration with Flow and gives the AI one job. That middle option gets skipped a lot, and it’s often the right answer.
The signal is simple. If you can name the 1 step needing judgment and everything around it is decided, you want a bounded AI step rather than an agent.
When Agentforce Is the Better Fit
Agentforce earns its place where the system has to interpret something before it can choose what to do.
Process characteristic | Why an agent fits |
|---|---|
Natural-language request | Intent has to be interpreted before any action is selected |
Incomplete input | The agent can ask for what’s missing instead of failing |
Several possible actions | Runtime context decides which one applies |
Multi-turn interaction | Earlier turns shape the next step |
Unstructured information | Reasoning and retrieval can work across content that has no schema |
State-dependent service | The right response depends on the customer or case situation |
Practical candidates include conversational service resolution, contextual sales assistance, multi-step information gathering, knowledge-driven employee support, and issue classification routing into different permitted actions.
Complexity on its own justifies nothing here. A complicated process with a knowable path is still a Flow problem, and a complicated process where only one step is ambiguous is a hybrid problem. Uncertainty about the route is what makes an agent the right call.
Two conditions strengthen the case. A long tail of request types needing dozens of configured branches, where an agent absorbs the variety instead. And content with no schema, such as free-text notes or email threads, where configured conditions can’t reach.
The clearest counter-signal is a process where someone can already write the rule. If a person can state the condition in a sentence, configure it and move on, an agent adds cost and variability without adding capability.
Customer-facing conversational work is where these conditions cluster most often, which is the territory Agentforce for service teams covers.
How Agentforce and Salesforce Flow Work Together
This is where most comparisons stop short. Salesforce supports traffic in both directions, and the pattern you choose changes cost, control and testing.
Agentforce calls Flow
User request → agent interprets intent → Flow action → controlled transaction
The agent decides what needs to happen. Flow carries it out with the validations, field updates and downstream processing already built and tested. Refunds, case escalations, account updates and order changes all fit this shape.
This is the pattern to reach for when the reasoning is genuinely uncertain but the execution must not be.
Flow calls Agentforce
Flow Builder includes a Run Agent element that invokes an agent from inside a Flow. Salesforce describes it as creating “an AI agent response for the specified user message.” It takes a user message and an optional Session ID, and returns an Agent Response, a Session ID, and a Structured Agent Response in version 1.1.0 and later.
Flow trigger → fixed steps → Run Agent → structured result → Flow continues
Use this where a known process has exactly 1 step that needs interpretation. A record is created, Flow validates the required fields, the agent reads an unstructured note, and Flow completes the defined business action with the result.
Two details matter before designing around it. The element is generally available in Enterprise, Performance, Unlimited and Developer editions, a narrower footprint than Flow Builder itself, so orgs on Professional or Pro Suite have Flow without this pattern. Salesforce also documents a second route through invocable actions: “Use invocable actions to call an Agentforce Service agent, Agentforce Employee agent, or Agentforce (Default) from a flow or Apex class.”
Flow uses a bounded AI step
A prompt template inside a Flow handles classification, extraction, summarization or generation as a single step. Flow keeps orchestration, the AI gets a narrow job, and nothing about the process becomes unpredictable.
Controlled agentic execution
Where a process needs reasoning but also needs guarantees, Agent Script imposes tighter execution control inside the agent, Flow and Apex hold any sequence that must stay fixed, and Agentforce Grid covers repetitive AI inference across existing record sets. Grid is an adjacent option rather than part of this comparison, but it’s worth knowing it exists before you build a loop or an agent for batch work.
Salesforce documents the Run Agent element and calling an agent from a Flow or Apex class as separate routes.
Scaling these patterns past a first use case changes the picture again, which the enterprise implementation guide covers. The architecture choice itself sits inside broader Salesforce AI solutions work.
Integration and External Systems: Who Controls the Path?
Both tools reach outside Salesforce, and current documentation is clear on that.
Flow connects to external systems through APIs, MuleSoft, HTTP callouts, external services and external system change-triggered patterns. Agentforce connects through Flows, Apex, MuleSoft APIs and external actions, with MuleSoft Agent Fabric and Agent Broker handling cross-enterprise agent coordination.
Both reach outside the platform. The difference is who picks the path.
Configured integration
Trigger → Flow → known API → result
Contextual integration
User intent → agent → selects a permitted integration action → API or Flow → result
In the first, you decided which system gets called. In the second, the agent decides at runtime from options you approved. That distinction drives your error handling, your credential design and your testing, far more than any question about reach.
Error handling changes the most. A Flow calling a known API handles that API’s failure modes, with retries written for one integration. An agent choosing among several needs sensible failure behavior for each, plus a defined response when a call returns nothing useful.
Credentials follow the same logic. The agent’s execution identity needs access to every integration action it might choose, which makes least-privilege design harder and more important at once.
Latency compounds it. An agent calling an external system mid-conversation adds that system’s response time to its own, and an API that performs fine in a nightly batch can feel slow in a live exchange.
Getting that connection layer reliable is its own workstream, and it sits at the center of Salesforce integration work.
Testing, Governance, Permissions, and Auditability
Operational control separates these tools more sharply than features do.
Flow testing
Salesforce supports automated tests for record-triggered, autolaunched and Data 360-triggered flows. You configure parameters and inputs once, and each run uses the same configuration. Salesforce recommends creating “a test for every path that the flow can take.”
The scope is bounded and honest about it: “a test can evaluate only whether a flow element ran and whether flow resource values are set as expected.” Assertions pass or fail against conditions you define. Add debug runs and runtime-context checks, since object and field access can differ depending on whether a flow runs in user or system context.
Agentforce access works differently and needs its own review. Permissions vary by agent type and by how each action is configured, so a custom action calling a Flow, an Apex class or a prompt template carries its own access requirements underneath the agent. Treating both tools as respecting one shared permission model is the mistake to avoid here.
Agentforce testing
Agent evaluation covers ground that path testing doesn’t reach. Whether the right subagent was recognized, whether the right action ran, whether retrieval pulled the correct content, and whether the response held up. Then the harder cases: ambiguous requests, invalid input, missing records, prompt-injection attempts and multi-turn conversations where an earlier turn changes the outcome.
As of Summer ’26, Salesforce states that “testing in Agentforce Testing Center is unmetered and doesn’t consume Einstein Requests or Flex Credits,” while “Data 360 queries from Agentforce Testing Center are still metered.” Confirm the current wording before you commit a testing figure, since this term has moved between releases.
Audit and control
Salesforce puts the difference plainly: “Traditional automation produces fully auditable execution trails through Flow Trigger Explorer and Apex logs. Agentforce-based end-to-end or hybrid patterns produce reasoning logs that provide transparency into agent decision making, but they require expertise to interpret.”
Both produce evidence. One replays a path, the other explains a decision, and your compliance team probably has a strong preference between those.
For sensitive work, the guidance is specific: “Agentic workflows operating at high density should incorporate explicit human approval or escalation gates for actions with irreversible consequences, such as financial transactions, regulatory submissions, or supplier commitments.” Approvals, Flow, Apex, Agent Script and human escalation are all available as the control layer.
The VALiNTRY360 Agentforce testing guide sets out what a full agent test plan contains, and an Agentforce readiness assessment is the usual starting point in a Flow-heavy org. Salesforce documents automated flow testing and Testing Center considerations separately.
Performance, Transaction Volume, Latency, and Cost
Performance and volume
Synchronous record-triggered flows complete inside the platform transaction in milliseconds. Agent inference time depends on reasoning depth and the modalities involved, so latency tolerance belongs in the decision alongside correctness.
The gap matters most where a user is waiting. A few seconds of reasoning is fine in a chat window, and it’s a problem behind a save button where someone expects the record to commit. Asking where the wait lands settles the question faster than any feature comparison.
Factor | Flow | Agentforce |
|---|---|---|
High transaction volume | Strong candidate | Assess whether reasoning is required |
Synchronous record updates | Strong candidate | Latency has to be acceptable |
AI consumption | Only where an AI feature is called | Applies to agent usage |
Unit of cost | Process elements and platform limits | Billable agent actions |
Maintenance | Flow and admin or developer effort | Agent, actions and monitoring |
Agentforce cost considerations
Salesforce currently lists Flex Credits at $500 per 100,000 credits, with a standard action consuming 20 credits and a voice action 30. At that rate a standard production action costs $0.10.
Conversations are $2, the Agentforce User License is $5 per user per month with Flex Credits required for metered usage, add-ons run $125 and $150 per user per month, and Agentforce 1 Editions start at $550 per user per month. Re-check these before you budget, since the terms move between releases.
Architecture affects the bill directly. An agent that interprets a request and calls 1 composite Flow consumes fewer billable actions than an agent that chains several separate actions to reach the same outcome. The saving comes from design, and the size of it depends entirely on your process, so model it rather than assuming a percentage.
Flow’s cost sits elsewhere. With no per-execution meter, the spend shows up as build and maintenance effort, the licenses connected features require, and the platform limits a high-volume design has to respect. Comparing a metered number against an unmetered one tends to flatter Flow in a way total project cost doesn’t support, so price the whole architecture: agent actions per request, the Flows underneath, the licenses both need, and the work of keeping each layer correct.
Our Agentforce pricing guide covers the product side in full, and Salesforce’s pricing page carries the current list rates.
Real Use Cases: Flow, Agentforce, or Hybrid?
Business process | Architecture to evaluate | Reason |
|---|---|---|
Record field update | Flow | Known trigger, known action |
Approval routing | Flow | Defined decision path with a required order |
Scheduled maintenance job | Flow | Repeatable event, no interpretation |
Ambiguous customer service question | Agentforce | Intent has to be interpreted first |
Guided issue resolution | Agentforce plus Flow | Reasoning, then a controlled transaction |
Sales inquiry qualification | Agentforce or hybrid | Context changes which action applies |
Case summary then fixed routing | Flow with a bounded AI step | 1 reasoning step inside a fixed process |
Refund request | Agentforce plus Flow and approval | Interpret the request, control the money |
Regulatory submission | Flow or Apex with approval gates | Execution control outweighs flexibility |
Bulk record classification | Agentforce Grid or bounded AI processing | Batch inference, not conversation |
External system update | Flow or hybrid | Depends on whether the target is known upfront |
Employee knowledge assistant | Agentforce | Conversational retrieval across content |
Where the 2 sections above sort work by category, the rows below name specific processes. The categories explain why a process leans one way, and the rows show where common ones usually land.
Treat these as starting points for evaluation. The same business process can land differently in 2 orgs depending on data quality, existing automation, compliance requirements and how much of the path is genuinely knowable in advance.
Read down the reason column rather than the process column, because that’s where the transferable logic sits. Rows resolving to Flow share a knowable trigger and a required order, while rows resolving to Agentforce share interpretation at the front.
Hybrid rows all have a seam where reasoning stops and execution has to be guaranteed. Finding that seam is the whole design exercise.
Two rows need extra care. Refunds and regulatory submissions both arrive in natural language and both carry consequences that shouldn’t sit behind a probabilistic decision, so the agent goes at the front for interpretation and a gated Flow or Apex action at the point of commitment.
Bulk classification is the other trap. It reads as an AI problem, which it is, but conversational agents are built for dialogue rather than throughput, so 40,000 records belong in a different pattern.
Should You Replace Existing Salesforce Flows With Agentforce?
Usually no, and the reason is architectural rather than sentimental.
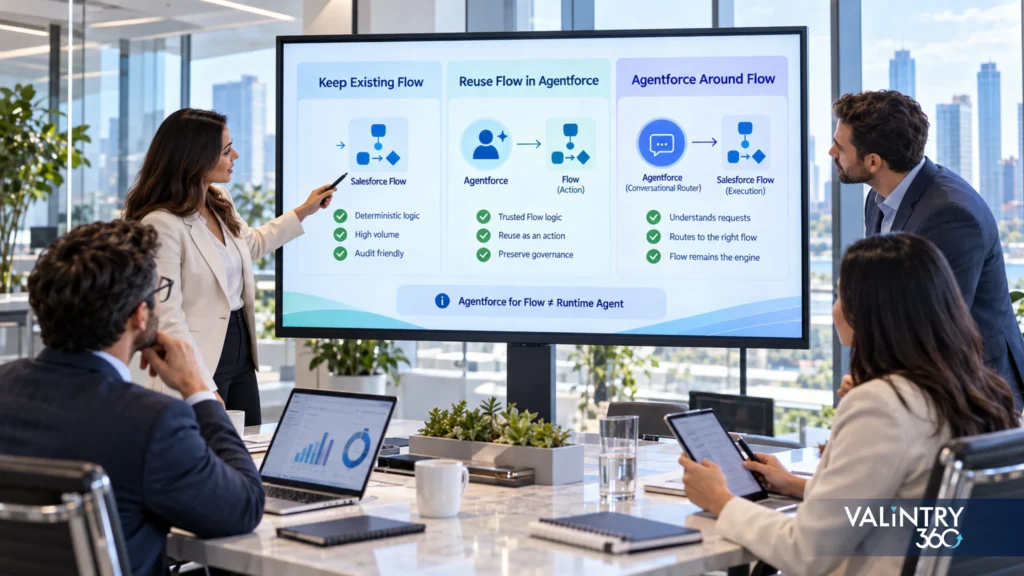
Keep the Flow as it is when the path is still fully defined, the business logic is correct, the action order matters, execution volume is high, or auditability is a requirement. A working deterministic process is an asset, and rebuilding it as agent instructions trades a guarantee for a probability.
Reuse the Flow inside Agentforce when the agent needs to invoke a business process you already trust. Exposing a tested Flow as an agent action gives you reasoning at the front and proven transaction logic underneath, without rewriting either.
Introduce Agentforce around the Flow when users need a conversational entry point, when intent determines which Flow should run, or when context has to be interpreted before execution begins. The agent becomes the router and the Flows stay the engine.
One thing worth separating clearly: Agentforce for Flow refers to AI assistance that helps admins draft, summarize and modify flows using natural language. That’s a completely different thing from an agent executing a business process at runtime.
Its release status is currently inconsistent across Salesforce’s own documentation. Salesforce Help describes drafting a Flow with Agentforce as “a pilot or beta service,” while Salesforce’s Admins blog for Spring ’26 says the feature is generally available.
The documented drafting limits are worth knowing either way. Generated flows run to about 6 elements, and advanced formulas, record variables, Apex actions, invocable methods and custom fields on standard objects are unsupported. Review, debug and test anything it produces before activating.
Where this review points to a bounded first agent rather than a rebuild, that narrow scope is what an Agentforce Quickstart covers.
Agentforce vs Salesforce Flow Decision Checklist
This is the VALiNTRY360 Salesforce automation decision worksheet. Work through it against 1 specific process rather than your automation estate as a whole, and the answers point toward an architecture to evaluate.
Question | Flow signal | Agentforce signal |
|---|---|---|
Can every meaningful path be defined before runtime? | Yes | No |
Is the input mainly structured? | Yes | Mixed or unstructured |
Does the process need multi-turn conversation? | Rarely | Yes |
Must actions run in a fixed sequence? | Yes | Use a hybrid control layer |
Is transaction volume very high? | Strong signal | Evaluate latency carefully |
Is low latency mandatory? | Strong signal | Evaluate carefully |
Does context determine which action runs? | Limited | Strong signal |
Would 1 AI step be enough? | Flow with a prompt template | A full agent may be unnecessary |
Does a sensitive action need approval? | Flow with approval gates | Hybrid with a gate |
Can an existing Flow handle the transaction? | Reuse it | The agent can call it |
Is the work bulk AI inference? | Consider an alternative pattern | Consider Agentforce Grid |
Is runtime conversation the main interface? | Limited | Strong signal |
Mostly Flow signals means configured automation, with AI available at a bounded step if one helps. Mostly Agentforce signals means the route genuinely varies at runtime. A mix means hybrid, where most real processes land.
Run the worksheet per process rather than per department, because the answers change inside a single team. A service organization can hold a fixed escalation Flow, a conversational front door and a bulk classification job at the same time, and each one lands somewhere different on the spectrum.
The worksheet is also worth rerunning after a process changes. Adding a channel, a system or a regulatory requirement moves several answers at once, and an architecture that fit last year may sit in a different place now. Where the terminology raises questions, the Agentforce glossary covers the vocabulary used here.
Salesforce Automation Case Studies Worth Reading
Architecture decisions read differently against delivered projects than against a checklist. If you want to see what configured automation looks like carrying real production load, these 5 VALiNTRY360 implementations each demonstrate a factor this article weighs.
1. TrialSpark: 77% Faster Ticket Resolution Across Clinical Trials
TrialSpark manages clinical trial enrollment and patient support across multiple concurrent studies. The build used Service Cloud, Salesforce Shield, Marketing Cloud, Sales Cloud, Experience Cloud and Salesforce Flow together, with work queues organized by trial stage, omni-channel routing to qualified clinical agents, escalation flows directing complex cases to clinicians, and AWS Connect telephony integrated alongside an internal enrollment application. The results recorded were 85% patient engagement in the first month of a new trial deployment, a 77% reduction in time to resolve study-related support tickets, and 20 hours saved per participant enrolled.
Key takeaway: Routing, escalation and queue logic are exactly the work that belongs in configured automation, and this build shows the volume that model sustains before any reasoning layer is involved.
Read the full case study: TrialSpark Clinical Trial Patient Operations
2. Real California Milk: 500 Annual Hours Reduced to 4
Real California Milk moved from SugarCRM to Salesforce Sales Cloud, with an ETL tool and custom automations handling quarterly Account and Contact imports plus the reconciliation logic around them, alongside MailChimp and Zoom integrations and custom management dashboards. Annual labor hours spent manually updating data fell from 500 to 4.
Key takeaway: Reconciliation logic has to produce the same result every run, which is the clearest case for keeping a process in a defined execution path rather than a reasoning layer.
Read the full case study: Real California Milk SugarCRM to Salesforce Migration
3. BIC Graphic: 27% More Pipeline and 7 Minutes Off Handle Time
BIC Graphic had no CRM and customer data fragmented across sales, marketing and service. The implementation covered Sales Cloud and Service Cloud with an integration into the existing ERP for order and fulfillment data, plus workflow automation across field sales, inside sales and quoting. Average handle time fell by 7 minutes and new pipeline opportunities rose by more than 27%.
Key takeaway: Configured automation reaching an external ERP under known conditions is the pattern this article calls configured integration, where the target system and the payload are both decided in advance.
Read the full case study: BIC Graphic Sales and Service Cloud Implementation
4. AthenaPsych: Compliance Errors Down 75% After an EMR Replacement
AthenaPsych, a mental health provider operating across New York State, replaced its Electronic Medical Record system with a Salesforce build on Health Cloud, Scheduler, Shield and Experience Cloud, integrating Change Healthcare and Vonage. Automated administrative workflows and real-time clinical documentation were central to the design. Within 6 months of phase 1, 80% of patients were scheduled on the first call, 68% completed intake within 7 days, CPT coding errors fell 69% and clinical compliance errors fell 75%.
Key takeaway: Regulated work rewards a defined path with measurable compliance outcomes, which is the same reasoning behind putting approval gates around any irreversible action an agent might reach.
Read the full case study: AthenaPsych Health Cloud EMR Replacement
5. All American Solar: 16% Quarterly Growth From a Bounded Scope
All American Solar needed Salesforce running without a dedicated administrator. The Quick Start mapped lead and opportunity processes to the company’s actual sales workflow, configured record types and roles, set up Lightning for Gmail synchronization, built dashboards for installation and KPI tracking, and delivered 4 hours of on-site training. The company reported 16% quarterly growth year over year afterward.
Key takeaway: A deliberately narrow first scope is the cheapest route to a working system, and the same logic applies to scoping a first agent against 1 measurable process.
Read the full case study: All American Solar Sales Cloud Implementation
Each of these ran on a defined scope with a measurable outcome attached, which is the evidence base the decision checklist above is built to produce before a process gets rearchitected.
FAQs About Agentforce vs Salesforce Flow
What is the difference between Agentforce and Salesforce Flow?
Flow executes a path you configure before runtime. Agentforce interprets a request at runtime and selects from permitted actions based on context, so the goal is fixed while the route varies.
Is Agentforce replacing Salesforce Flow?
No. Salesforce’s current architecture guidance positions them as complementary, and Agentforce frequently calls Flows to carry out the actual transaction work.
When should I use Salesforce Flow instead of Agentforce?
When every branch can be defined in advance, action order must be guaranteed, volume is high, or low latency is a hard requirement.
When should I use Agentforce instead of Salesforce Flow?
When the next action depends on interpreting natural-language input, conversation history or retrieved content rather than on conditions you can configure upfront.
Can Agentforce call a Salesforce Flow?
Yes. A Flow can be exposed as an agent action, letting the agent handle reasoning while the Flow performs the controlled business process underneath.
Can Salesforce Flow call an Agentforce agent?
Yes. Flow Builder’s Run Agent element sends a user message to an agent and returns the response, including a structured response in version 1.1.0 and later. It’s available in Enterprise, Performance, Unlimited and Developer editions.
Can an existing Flow be reused as an Agentforce action?
Yes, and that’s usually the better move than rebuilding the logic as agent instructions, since the Flow already carries tested transaction behavior.
Is Agentforce more expensive than Salesforce Flow?
Agentforce carries metered usage that Flow doesn’t, though Flow’s connected features need their own licenses. Compare the total architecture rather than the 2 products in isolation.
Does Salesforce Flow require Data 360?
No. Flow runs without it, though specific Data 360 features inside Flow require Data 360 users.
Does Agentforce require Data 360?
It depends on the use case. Agentforce Data Library requires it, while an agent grounded only in Salesforce records and Flows may not.
Which is easier to test, Agentforce or Salesforce Flow?
Flow, because tests assert whether elements ran and values match expectations along a defined path. Agent testing evaluates behavior across many possible inputs, which takes more design work.
Which is better for high-volume Salesforce automation?
Flow. Salesforce’s own architecture guidance rules Agentforce out for high-volume synchronous record processing wherever latency is a binding constraint.
Which is better for regulated business processes?
Configured automation with explicit approval gates, because it replays a defined path. An agent can still front the process, with Flow or Apex controlling the irreversible action.
What is Agentforce for Flow?
AI assistance for admins building flows: drafting, summarizing and modifying them in natural language. Its status reads as beta in Salesforce Help and generally available in Salesforce’s Admins blog, so verify before relying on it.
When should I combine Agentforce and Salesforce Flow?
When part of the process needs interpretation and another part needs guaranteed execution, which describes most substantial service, sales and operations workflows.
Related Posts
Salesforce Release Management Framework
TL;DR Salesforce changes come from everywhere. Admins tweak page layouts. Developers ship Apex.Integrations push metadata changes of their own.A handful of other changes stack on top of that every week:Flows get rebuilt mid-quarterPermissions shift as teams reorganizePackage updates land on…
Agentforce vs Salesforce Flow: Which Should You Use…
Your Salesforce org may already depend on Flow for record updates, approval routing, notifications, scheduled jobs, guided screens, and other repeatable processes. Each path is configured in advance, so the system follows the same rules whenever the same conditions appear.Agentforce…
Do You Need Salesforce Data 360 Before Agentforce?
Salesforce sits Data 360 underneath several Agentforce capabilities, so the advice you'll hear is that Data 360 comes first. That advice is accurate and close to useless, because "Data 360 first" describes 2 very different projects. One is a provisioning…