- Salesforce Consulting Services
Your Salesforce org probably already holds customer history, working automation, integrations, reports, custom code, and months of project effort. That’s exactly why a troubled implementation deserves a recovery decision based on evidence, not a reflex to tear it down.
A Salesforce implementation failure can show up before go-live or years after it. Different symptoms come from different causes, and chasing them one at a time without a diagnosis usually makes things worse. A fix aimed at the wrong cause can look like progress while the real problem keeps running underneath it.
This guide walks through how to assess a failed Salesforce implementation, decide what’s worth keeping, repair what’s broken, and restart delivery on a foundation that won’t fail the same way twice.
The goal is a Salesforce implementation that supports the business reliably, with the parts worth preserving intact and the parts that were always going to cause problems replaced on purpose. Perfection was never the bar.
What Does Salesforce Implementation Failure Actually Look Like?
Salesforce implementation failure rarely announces itself with a single event. It shows up as a pattern, and the pattern tells you where to look first.
Failure state | What the business sees | What needs investigation |
|---|---|---|
Project stall | Deadlines keep moving | Scope, ownership, dependencies |
Weak go-live | Users remain in spreadsheets | Process fit, training, usability |
Unstable org | Small changes trigger defects | Architecture, automation, testing |
Data failure | Reports and records lose trust | Migration, duplicates, ownership |
Integration failure | Systems disagree or stop syncing | APIs, mapping, system of record |
Delivery failure | Releases create recurring problems | Environments, testing, deployment |
Technical go-live vs business success
A Salesforce org can go live on schedule and still fail the business. Users log in, but they keep a spreadsheet open next to Salesforce because the org doesn’t capture what they actually need to track. Reports run, but nobody trusts the numbers enough to act on them.
Go-live proves the platform was deployed. It doesn’t prove the intended business process actually moved onto it.
Identify the failure stage first
Before you diagnose anything, classify where the project currently sits:
- Stalled before launch
- Unstable during rollout
- Weak after go-live
- Deteriorating long after launch
Each stage calls for a different first move. A stalled pre-launch project needs a scope and requirements review, while a years-old org that’s slowly degrading needs a technical debt and data audit first.
Knowing your stage keeps you from applying the wrong fix to the right problem. A rescue built for a weak go-live won’t help a project that’s never launched at all.
Why Salesforce Implementations Fail: 7 Recurring Salesforce Implementation Challenges
Most Salesforce implementation challenges trace back to one of 7 recurring causes. For each one, look at the cause, the symptom you’d actually notice, and the evidence that confirms it.
1. Requirements were weak or incomplete
Cause: The team configured Salesforce before it understood how the business actually works.
Symptom: Users constantly ask for “one more field” or “one more automation” to cover a process nobody documented up front.
Evidence to collect: Original requirements documents, stakeholder interview notes, and a comparison between what was scoped and what users do daily.
2. Scope kept expanding during delivery
Cause: New requests entered the build without a prioritization gate, so core functionality competed with add-ons for the same delivery time.
Symptom: The project timeline stretches repeatedly while the original must-have features remain unfinished.
Evidence to collect: Change logs, sprint or phase plans, and a list of features added after the original scope was signed off.
3. Architecture became difficult to maintain
Cause: Overlapping Flows, duplicated logic, and undocumented dependencies accumulated without anyone tracking the resulting complexity.
Symptom: A single field update in one place breaks 3 unrelated processes somewhere else.
Evidence to collect: Flow and Apex inventories, dependency maps, and recent defect tickets tied to automation conflicts.
4. Data quality broke trust
Cause: Migration rules, manual entry, and missing validation let duplicates and incomplete records into the org.
Symptom: 2 reports pulling from the same objects show different numbers, and nobody can say which one is right.
Evidence to collect: Duplicate counts, required-field completion rates, and a sample audit of records against their source system.
5. Integrations lacked clear ownership rules
Cause: Nobody defined which system is the source of truth for shared fields, so conflicting updates overwrite each other silently.
Symptom: A customer record looks correct in one system and wrong in Salesforce, with no error message anywhere.
Evidence to collect: Integration logs, field-level mapping documentation, and a list of which system owns which field.
6. Testing and releases were too weak
Cause: Changes went straight into production without a consistent testing stage, so defects reached users instead of a sandbox.
Salesforce’s own deployment best practices guidance advises using dedicated development environments and multiple testing stages for application changes, rather than building significant changes directly in production.
Symptom: Releases correlate directly with a spike in support tickets.
Evidence to collect: Deployment history, test coverage reports, and incident timestamps compared against release dates.
7. Users never adopted the operating process
Cause: Training covered how to click through Salesforce screens, not how to do the job inside them.
Symptom: Managers still ask for status updates over email because they don’t trust what’s in the system.
Evidence to collect: Login and activity data, manager interviews, and a list of workarounds teams built outside Salesforce.
Triage Salesforce Implementation Problems Before Adding New Work
The first recovery move is a pause. Diagnosis gets harder when admins, developers, and vendors keep changing the environment you’re trying to assess.
That’s a hard instinct to fight. When something is visibly broken, the natural response is to start fixing things immediately.
But a fix applied mid-diagnosis becomes a new variable in the data you’re trying to read, and it can hide the actual root cause behind an unrelated improvement. A short, deliberate pause almost always saves more time than it costs.
Address high-impact incidents first
Some issues can’t wait for a full assessment:
- Production outages
- Security exposure
- Records being corrupted
- Revenue-blocking workflows
- Service processes that can’t complete
- Integration failures affecting core operations
Fix these immediately. Everything else goes into a queue.
Place lower-priority changes into a controlled queue
Hold off on anything that isn’t actively breaking the business:
- Feature requests
- Layout changes
- New packages
- Broad automation rewrites
- Speculative custom work
- Low-impact backlog items
None of this work disappears. It just waits until the stabilization window closes.
Immediate triage checklist
For every open issue, record:
- Affected process
- Affected users
- Business impact
- First known occurrence
- Recent changes
- Relevant Flow or code
- Integration activity
- Current workaround
- Current owner
The output of triage is 2 lists: a short one for production issues that need immediate work, and a longer recovery backlog for everything else, once it’s been properly assessed.
Build a Reliable Recovery Baseline Before the Full Audit
Before you run a deep audit, give the recovery team a known starting point. Skipping this step means every finding gets argued over instead of acted on.
Capture the current Salesforce state
Inventory what’s actually running:
- Salesforce products in use
- Environments
- Objects
- Active automation
- Apex
- Lightning components
- Packages
- Integrations
- Scheduled jobs
- Integration users
This inventory is what the audit team checks its findings against, so it needs to reflect what’s actually deployed, not what the original project plan said would be deployed.
Collect project evidence
Pull together what exists on paper:
- Original scope
- Requirements
- Process diagrams
- Architecture records
- Test results
- Migration files
- Deployment history
- Support tickets
- Training materials
Whatever’s missing from this list is itself a finding, since a recovery with no original requirements on file is diagnosing blind.
Map current ownership
Someone needs to own each of these areas, even if that ownership has drifted:
- Business processes
- Salesforce platform
- Data
- Integrations
- Deployments
- Security
- Reporting
Where an area shows no clear owner, write down who’s covering it informally today, since that’s usually who inherits it permanently if nobody intervenes.
Record known gaps
Write down what’s actually missing, separate from what people assume is missing. Assumptions get treated as facts once they’re repeated a few times, and that’s how audits chase the wrong problem.
A common example: someone insists the integration “never worked right,” but nobody can point to a specific failed transaction or an error log entry. That belief might be correct, but until it’s tested against evidence, it’s a lead, not a finding. Keep leads and findings in separate columns so the audit team knows which claims still need to be checked.
This baseline becomes the reference point the org audit works from. Every finding in the next phase gets checked against it, which is what keeps the audit grounded in the current state of the org rather than in whatever story has built up around it over time.
Run a Salesforce Org Audit Across 7 Recovery Areas
This is the deepest part of the recovery process, and it’s worth doing properly. A shallow audit produces a shallow fix.
Checking whether Salesforce “works” isn’t the same as auditing it. Functional checks confirm that a screen loads or a workflow completes, but they don’t confirm the data behind it is trustworthy or that the automation producing it is stable. The 7 areas below cover the ground a single functional check misses.
1. Business-process audit
Review the original goals, current workflows, user roles, offline workarounds, changed requirements, and process exceptions that have accumulated since launch, the same groundwork covered under Salesforce Consulting Services.
2. Data-model audit
Review objects, relationships, fields, naming conventions, record ownership, and unused metadata. A data model built for a 50-person pilot often can’t carry a 500-person rollout without breaking, which is exactly the kind of structural mismatch a recovery audit needs to catch before it gets blamed on user error.
3. Automation and code audit
Review Flow, Apex, triggers, validation rules, Lightning components, dependencies, and error handling. Salesforce’s guidance on Flow fault paths recommends adding fault paths for elements that can fail, along with dedicated troubleshooting steps for runtime failures.
4. Data audit
Check completeness, accuracy, duplicates, stale records, migration defects, and relationships. Salesforce’s own data quality guidance connects clean records directly with user trust in the system.
5. Integration audit
Document every connected system, the data it exchanges, the direction of that exchange, the system of record, authentication method, error handling, retry behavior, and monitoring in place.
6. Security audit
Review profiles, permission sets, sharing rules, administrator access, integration users, sensitive fields, and authentication settings. Use Salesforce Health Check specifically for this step. Salesforce’s own Security Health Check documentation describes it as a tool for comparing org security settings against a baseline standard, not as a measure of business logic or data quality.
7. Delivery audit
Review source control, sandboxes, test environments, UAT process, deployment history, release ownership, and documentation.
This 7-area review is the same scope covered under Salesforce Remediation Services, which treats automation, integrations, user activity, and data condition as one assessment rather than 7 separate reviews.
Keep, Repair, Rebuild, or Retire Each Salesforce Component
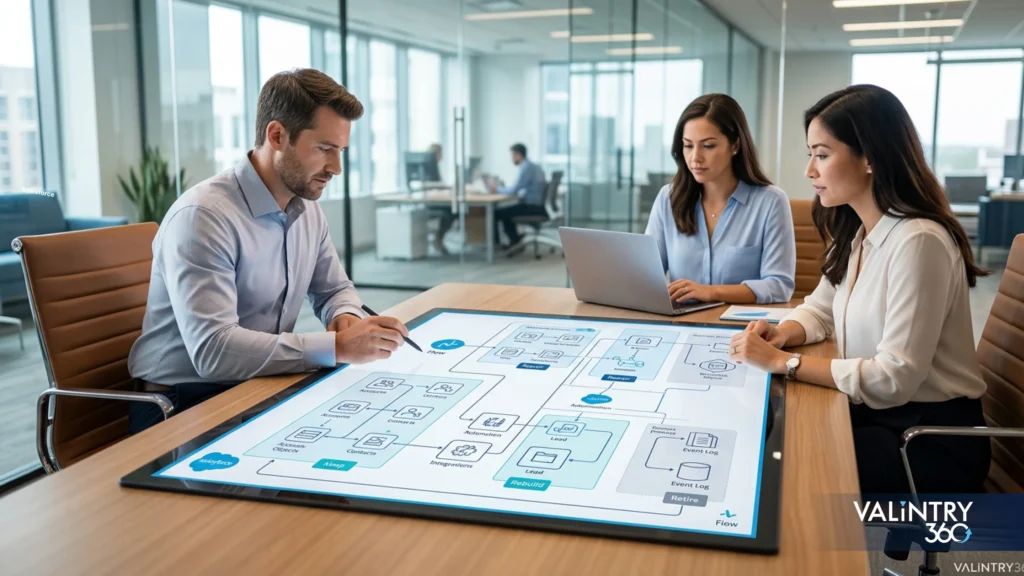
This is the framework that answers the “without starting over” part of the title. A troubled implementation almost always contains real, working value alongside its problems. The job is telling them apart.
Keep
Choose this when the component supports a current business requirement, behaves predictably, has understood dependencies, and can stay maintainable without special handling.
Repair
Choose this when the requirement remains valid, the underlying design is still sound, the defect has a clear boundary, and the repair effort is reasonable relative to the value.
Rebuild
Choose this when the requirement remains necessary, but the current design keeps causing the same failure. Patching it again would just preserve the structural problem for another cycle.
Retire
Choose this when the business requirement has disappeared, another component already does the same job, usage is negligible, or continued maintenance has no current justification.
Decision matrix
Question | Keep | Repair | Rebuild | Retire |
|---|---|---|---|---|
Business requirement remains active | Yes | Yes | Yes | |
Existing design remains sound | Yes | Yes | ||
Local correction solves the defect | Yes | |||
Structural weakness exists | Yes | |||
Current business purpose has ended | Yes |
Apply this to objects, fields, Flows, Apex, integrations, packages, reports, and permission design, one component at a time.
Technical debt is usually what tips a component from Repair into Rebuild. A defect that’s cheap to patch today but expensive to touch again next quarter is a structural problem wearing a small one’s clothes, and this framework is what catches it before another patch gets scheduled on top of it.
Repair the Business Journeys That Carry the Most Operational Risk
Once you know what to keep, fix, rebuild, or retire, the recovery backlog needs an order. Ticket age is a weak way to prioritize. Business impact isn’t.
Map complete journeys
Look at entire paths, not isolated tickets:
- Lead to opportunity
- Quote to order
- Case intake to resolution
- Customer onboarding
- Renewal
- Order handoff
- Service escalation
Each of these crosses multiple objects and teams, which is exactly why a single ticket-level fix rarely resolves one on its own.
Score each journey using 5 factors
Factor | Recovery question |
|---|---|
Business impact | What happens when the process fails? |
Data/security risk | Can failure damage records or access? |
Dependency | Which other work relies on this? |
User reach | How many roles depend on it? |
Repair effort | How much controlled work is required? |
Fix dependencies before symptoms
Work in an order that respects what actually depends on what: record ownership, then process logic, then automation, then integrations, then reporting, then training. Repairing a downstream step before its upstream dependency is fixed just moves the same defect one step closer to the user.
Reset the old backlog
Go through old tickets and remove anything tied to a retired requirement or a duplicate request. A troubled implementation often has hundreds of open items, and a good share of them describe a process that no longer exists.
Recover Data, Integrations, Security, and Reporting Trust
Treat this as 4 separate workstreams. Fixing one doesn’t automatically fix the others, even though they usually show up as a single complaint: “I don’t trust Salesforce.”
Data recovery
Once the data audit above has flagged what’s wrong, repair works backward from the defect to its source: deduplicate the affected records first, then correct the migration rule, web form, or missing validation rule that’s still creating new ones. Fixing the records without fixing the source just means auditing the same fields again next quarter.
This same mapping, transformation, duplicate handling, loading, and validation work is what Salesforce Data Migration Services covers as a standalone specialty, worth separating out when the data problem is bigger than the rest of the recovery.
Integration recovery
For every major connection, document the following:
Item | Question |
|---|---|
Purpose | Why does the connection exist? |
Data | What moves? |
Direction | Which way does it move? |
Ownership | Which system controls each field? |
Failure | What happens when the request fails? |
Recovery | How is the transaction retried or repaired? |
Monitoring | Who sees the failure? |
Salesforce’s reliability guidance places the responsibility for application-level monitoring and recovery on the solution design itself, alongside the platform infrastructure underneath it.
This kind of connection audit and repair falls under Salesforce Integration Services, including the retry and monitoring work most teams skip the first time around.
Security recovery
Where the security audit above turned up privileged users, inactive accounts, or sharing rules nobody can explain, recovery means actually closing those gaps: deactivate unused accounts, tighten sharing rules to match current roles, and re-issue integration credentials that were never scoped down after go-live.
Reporting recovery
Trace important KPIs back through the full chain: dashboard, then report, then formula, then field, then source process. Repair the definitions and source data first. Rebuilding the dashboard before that just moves the same wrong number to a nicer layout.
Restart Salesforce Development, Testing, and Releases From a Controlled Baseline
A recovery can fail again if the delivery process that caused the original problems stays exactly the same. Fixing today’s defects without fixing how defects get introduced just buys time.
Re-establish source control
Determine which metadata state actually represents your approved baseline, since production, sandboxes, and old backups often drift apart from each other over time. Whichever version you pick becomes the reference every future deployment gets measured against, so document it before making another change.
Define environment roles
Document what belongs in developer environments, integration testing, UAT, staging where it’s used, and production, and assign each environment an owner who’s actually accountable for enforcing that boundary. Most teams already have the sandboxes they need. They just haven’t agreed on what each one is for, so changes end up wherever’s fastest at the moment instead of wherever’s correct.
Rebuild testing around business risk
Cover unit tests, Flow tests, integration tests, regression tests, role-based UAT, and volume testing where it matters. Salesforce’s guidance on testing Flows before activation recommends testing outcomes, boundary conditions, permissions, and failure paths, since a single happy-path run rarely catches what actually breaks in production.
Restore release governance
Define a release owner, an approval step, deployment evidence, smoke testing after each release, rollback steps, and a defined emergency-change process for the incidents that genuinely can’t wait.
Track technical debt as a line item
Technical debt should be a visible backlog entry with an owner, a stated business impact, and a treatment plan, matching the code quality patterns Salesforce’s own architecture guidance recommends for tracking it.
This kind of custom technical rebuild work, when Apex or Lightning components need more than a patch, falls under Salesforce Development Services and Salesforce Customization Service.
Restore User Adoption, Ownership, and Salesforce Governance
Technical repair needs an operating model built around it, or the org drifts back into the same condition within a year or two.
Diagnose why users left Salesforce
Investigate workflow friction, duplicate entry, missing capabilities, unreliable data, unnecessary required fields, training gaps, spreadsheet dependence, and manager behavior. Training alone rarely fixes all 8 of these at once, because they usually aren’t the same root cause.
Assign permanent ownership
Someone needs a name attached to each of these, not a shared inbox: business process, platform, data, integration, security, backlog, release, and support. That ownership has to survive past the recovery project itself, or the same gaps reopen within a year.
This kind of ongoing platform, backlog, and release ownership, once the immediate recovery work is finished, is what Salesforce Managed Services covers.
Train around real work
Retraining after a failed rollout needs to fix the specific gap the original training left, which is usually screen mechanics without job context. Build sessions around the real scenarios a role handles every day, with the data quirks and workarounds particular to your org, rather than a generic product tour that shows every button without explaining when to use it.
Measure adoption through completed work
Login counts tell you someone opened Salesforce, not that it’s working for them. Better measures include opportunity freshness, case completion rates, data completeness, workflow completion, use of approved reports, and the number of offline workarounds still in use.
Salesforce’s operational excellence guidance treats governance and maintainability as connected concerns rather than separate initiatives, and its own adoption guidance ties lasting adoption to change management, executive support, and direct user involvement in the design process.
Salesforce Remediation vs Partial Rebuild vs Full Reimplementation
The keep, repair, rebuild, or retire framework above works component by component. This section zooms out to the project level: once you’ve run that framework across every object, Flow, and integration, the pattern in the results tells you whether you’re looking at targeted remediation, a partial rebuild, or a full reimplementation.
Recovery path | Suitable condition | Existing work preserved | Main work created |
|---|---|---|---|
Targeted remediation | Problems have clear boundaries | High | Repair and regression testing |
Partial rebuild | Several workstreams have structural problems | Medium to high | Redesign and transition |
Full reimplementation | Foundational design can’t support current requirements | Lower | New build, migration, retesting, retraining |
Targeted Salesforce remediation
Use this when the foundation remains usable and the defects you’ve found have defined boundaries. This is the outcome the keep/repair framework points to most often.
Partial rebuild
Use this when individual areas, such as automation, the data model, integration, or security, need a genuinely deeper redesign, while the wider org still supports the business.
Full reimplementation
Consider this when the existing foundation would create an unacceptable ongoing repair and operating burden no matter how much you patch it. When the rebuild reaches beyond Salesforce into how the business runs more broadly, that wider redesign is what Digital Transformation Solutions covers alongside the platform rebuild.
Decision inputs
Base the choice on evidence from your current business requirements, architecture, data condition, dependencies, technical debt, migration burden, user transition cost, and long-term maintenance, not on frustration with how the last project went. What a fresh build actually looks like, when reimplementation is genuinely the right call, is covered under Salesforce Implementation Services.
Whichever path you choose, the audit findings are what make it defensible when someone later asks why the org wasn’t just rebuilt from zero.
How to Estimate Salesforce Recovery Cost and Timeline
Skip any claim that every Salesforce rescue costs a fixed dollar range. Recovery cost depends heavily on how much of the existing implementation remains usable, and that number is different for every org.
Recovery cost model
A more honest cost framework looks like this:
Recovery estimate = assessment + stabilization + remediation work + data/integration correction + testing + user recovery + post-release support
Cost drivers
Several factors move that number up or down: org size, number of user groups, custom code volume, automation volume, integration count, data condition, missing documentation, release maturity, security requirements, and how much of the existing work can actually remain.
A 200-user org with clean data and 2 well-documented integrations recovers faster and cheaper than a 100-user org with a decade of undocumented Apex and 6 integrations nobody fully understands.
Org size alone is a poor predictor of recovery cost. Condition is the better one.
Timeline drivers
Timeline depends on audit depth, dependency discovery, SME availability, data cleanup scope, integration testing, UAT scheduling, release windows, and whether a partner handoff is part of the process.
Budget comparison
Path | Main cost areas |
|---|---|
Remediation | Audit, repair, testing |
Partial rebuild | Audit, redesign, rebuild, transition |
Reimplementation | New solution, migration, integrations, retraining, cutover |
Keep every estimate tied to stated assumptions about scope and condition. An estimate without assumptions attached is just a guess with a dollar sign on it.
How to Hand Off a Failed Salesforce Implementation to a New Partner
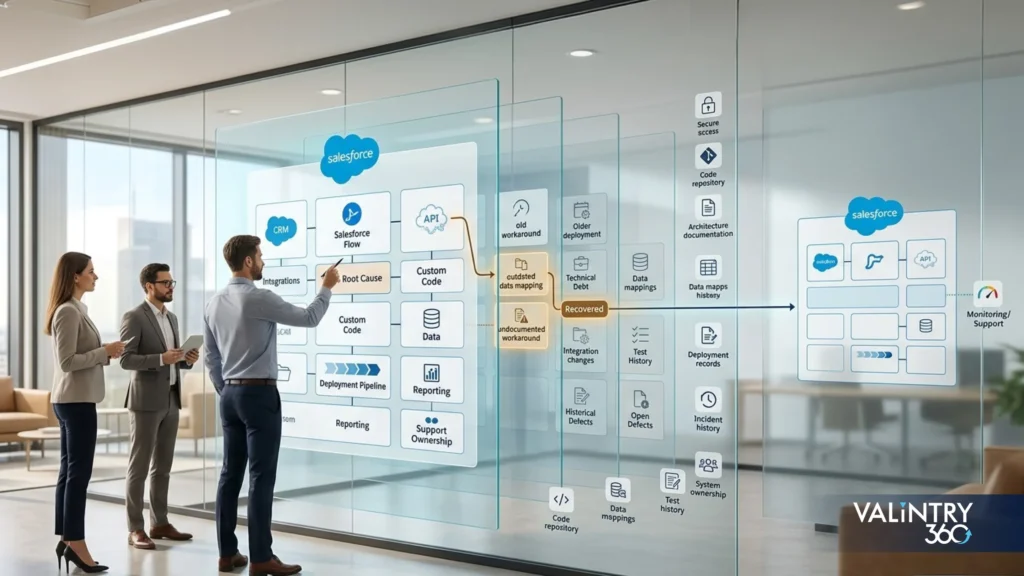
Replacing a Salesforce partner mid-recovery is common, and it works far better with a clean handoff than a rushed one.
Transfer technical access
Include Salesforce environments, code repositories, CI/CD tools, middleware, integration credentials, and vendor accounts.
Transfer project evidence
Request requirements, architecture records, data mapping documentation, test results, deployment history, open defects, the technical-debt backlog, and any known workarounds the team relies on.
Transfer operating knowledge
Document who the business owners are, who owns each integration, what the release process looks like, the incident history, and who currently holds support responsibilities.
Once the handoff requirements are clear, it’s worth knowing what a remediation partner typically does with that information. A structured remediation engagement generally works through org assessment, root-cause diagnosis, automation and integration repair, data condition work, and testing, in that order, starting from the same audit this guide just walked through. Skipping straight to repair without that audit is how a second partner ends up repeating the first one’s mistakes.
Day-to-day support after recovery is a separate role from the recovery itself, and it’s worth deciding upfront who holds it. Salesforce Managed Support Services is the category this falls under when the same team that diagnosed the failure stays accountable for the org afterward, rather than handing it off a second time.
For a business evaluating a partner switch, the underlying question stays the same regardless of who does the assessment: what does the current org actually look like, what’s worth keeping, and what would a fresh set of eyes find that the previous partner missed. Answering that honestly is what separates a real recovery from another year of the same problem repeating under new management.
Related VALiNTRY360 Case Studies Worth Reviewing
Some of the recovery and optimization patterns in this guide show up in real client work. These 5 VALiNTRY360 case studies cover legacy-system replacement, data quality repair, and multi-cloud complexity relevant to a troubled Salesforce implementation.
Ravago: Salesforce Marketing Cloud Optimization. An existing Marketing Cloud instance built for a different audience couldn’t support a new direct-to-consumer segment, so the underlying data model and automations were rebuilt rather than layered on top, generating $500,000 in new revenue within 3 months.
Real California Milk: SugarCRM to Salesforce Migration. A legacy CRM with no single source of truth required manual quarterly reconciliation that ate roughly 500 hours a year, cut to 4 hours a year after an automated migration and data cleanup.
AdventHealth University: Salesforce Implementation. 25 years of alumni records scattered across disconnected systems were migrated as a data quality exercise rather than a straight transfer, since a system nobody trusts is a system nobody uses.
AthenaPsych: Salesforce Health Cloud EMR Replacement. A legacy EMR forced constant reconciliation between separate clinical and operational records, resolved by replacing rather than integrating it, then connecting Scheduler, Shield, and Experience Cloud around the new foundation.
BIC Graphic: Sales Cloud and Service Cloud Implementation. Field sales, inside sales, quoting, and service each kept disconnected records with no shared system of record, fixed by combining Sales Cloud, Service Cloud, and full ERP integration into one platform.
Reading a real project’s starting condition next to its outcome is a useful gut check before finalizing your own keep, repair, rebuild, or retire decisions.
Frequently Asked Questions
Can a failed Salesforce implementation be fixed without starting over?
Usually, yes. Most troubled orgs have salvageable foundations once you audit them properly first. Use the keep, repair, rebuild, or retire framework component by component instead of writing off the whole implementation, since most failures are contained rather than total.
What are the most common signs of Salesforce implementation failure?
Users working around Salesforce instead of in it, reports that don’t match between departments, integrations that silently disagree, and releases that reliably create new defects. Any one of these points to a different root cause worth investigating on its own.
Why do Salesforce implementations fail?
The 7 recurring causes are weak requirements, uncontrolled scope growth, unmaintainable architecture, poor data quality, unclear integration ownership, weak testing and release practices, and low user adoption. Most failures involve more than one of these at once.
What should we do first when Salesforce implementation problems appear?
Stabilize before you diagnose. Fix anything actively breaking the business immediately, hold nonessential changes in a controlled queue, and gather evidence on the current state before you commit to any repair plan, since fixes made mid-diagnosis tend to obscure the real root cause.
What does a Salesforce implementation rescue include?
A structured assessment, triage of urgent issues, a baseline of the current state, an org audit across 7 areas, a salvage decision for each component, remediation work, testing, and a partner handoff process where a new team is taking over.
What should a Salesforce org audit include?
Business processes, the data model, automation and code, data quality, integrations, security, and delivery practices, each checked against the requirements the org was originally built to support. Skipping any one of these 7 areas leaves a blind spot the eventual fix won’t catch.
What is Salesforce technical debt?
Configuration, automation, or code that works today but makes future changes riskier or more expensive than they should be. It should be tracked as a visible backlog item, not treated as an informal understanding a few admins carry around.
How do we decide which Salesforce customizations to keep?
Ask whether the business requirement is still active, whether the underlying design is still sound, and whether a local fix solves the current problem. If all 3 hold, keep it or repair it rather than rebuilding it.
When should Salesforce Flow or Apex be rebuilt?
When the requirement is still valid but the current design keeps producing the same defect after repeated fixes. Repeated failure after patching signals that the structure itself needs to change, since fixing only the latest bug leaves the same design flaw in place for the next cycle.
How can bad Salesforce data be repaired?
Diagnose the source first, whether that’s migration rules, manual entry, web forms, or missing validation, then clean the existing records, and put prevention controls in place at that same source so the same defects don’t quietly reappear next quarter.
What should we do when Salesforce integrations keep failing?
Document ownership, review error logs, check field mapping, confirm authentication, and add retry logic and monitoring where none currently exists. A technically connected integration can still produce a failed business process if nobody is actually watching it or accountable when it breaks.
Should we change Salesforce implementation partners during recovery?
Consider it when the current partner lacks the audit skills a proper recovery needs, but only after a clean handoff of access, documentation, and open issues. A rushed switch just adds a second knowledge gap on top of the first one.
When does Salesforce need a full reimplementation?
When the audit shows a structural problem, such as a fundamentally unsuitable data model or an architecture that can’t support current requirements, not simply because the current org feels old or frustrating to work in.
How much does Salesforce implementation recovery cost?
It depends on assessment scope, stabilization needs, remediation workstreams, data and integration correction, testing, and how much of the existing implementation remains usable versus needing rework. There’s no universal number that applies across every org, whatever a generic rescue price list might claim.
How do we prevent another Salesforce implementation failure?
Keep technical debt visible, restore real release governance, track adoption through completed work rather than logins, and assign clear ownership across the business process, platform, data, and delivery process, since code ownership alone won’t stop the same failure from returning.
Related Posts
- Salesforce Consulting Services
Why Salesforce Integrations Fail – and How to…
Introduction: When an Integration Stays Online but the Business Process Breaks A Salesforce integration can pass every technical check and still fail the business that depends on it. The connection authenticates and the API returns success, while records still arrive…
- Salesforce Consulting Services
Why Salesforce Reports Can’t Be Trusted
A VP of Sales opens the pipeline dashboard on Monday and sees $4.2M. RevOps runs the saved pipeline report an hour later and gets $3.8M. Finance walks into the forecast meeting carrying $3.1M.All 3 numbers came out of the same…
- Salesforce Consulting Services
Salesforce Consulting RFP Template & Partner Scorecard
Ask 2 Salesforce firms to quote the same project and you can get 2 very different prices back. One assumed a lighter data migration. Another built in more testing, more training, or a longer support period.Neither one lied. They filled…