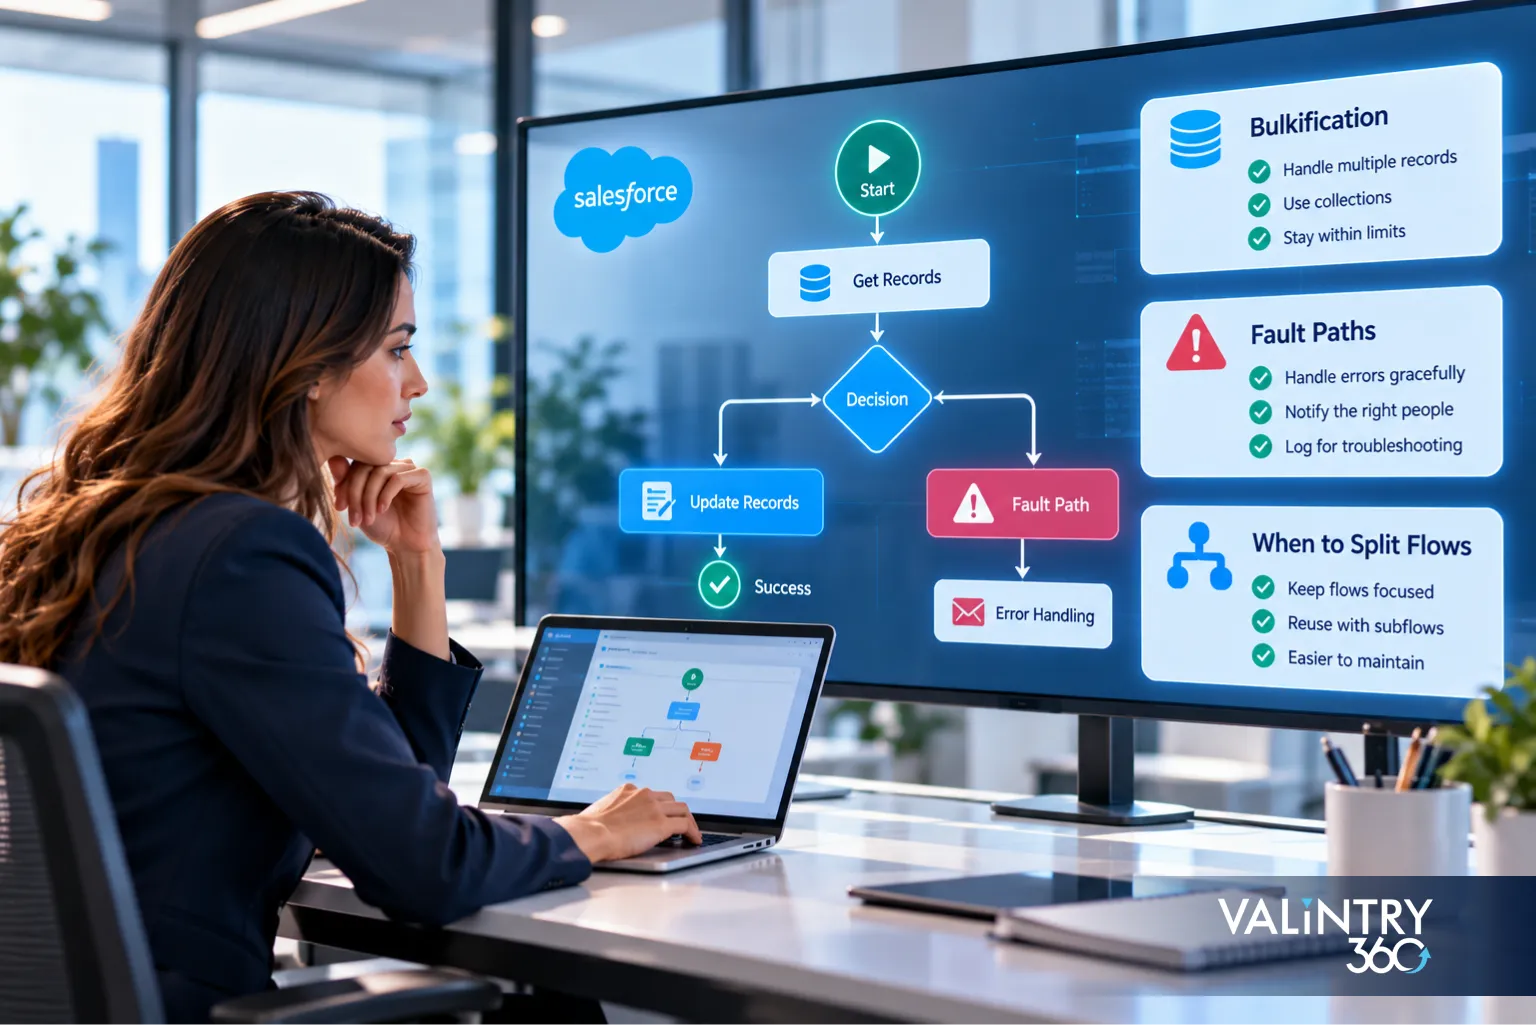
A flow that works on one test record can still fail the first time someone loads 500 records. It can also fail quietly, with nobody told, or grow for three years until no one wants to edit it. Good Salesforce automation helps prevent all three problems with a few repeatable habits. Those habits start with thinking beyond the immediate task: how many records the flow might process, what should happen when something goes wrong, and how another admin will understand the logic months later. Teams that build these habits early are better prepared to troubleshoot issues and manage changes. Teams that skip them often discover the gaps during a data load, a release, or an urgent business request.
In this guide, we explain how to bulkify flows, build useful fault paths, and decide when to split one flow into several. We also cover entry conditions, trigger order, subflows, testing, and naming standards, with a focus on making automation easier to maintain as your Salesforce environment grows. You will learn which limits matter, which patterns to avoid, and where Apex becomes the better choice. We look beyond whether a flow completes successfully to consider how it handles larger workloads, unexpected inputs, and future changes. Each section gives you a practical rule you can apply to your own flows today, whether you are building new automation or reviewing flows already in production.
TL;DR
Build Flows for Volume, Not Single Records
Flows run inside shared transaction limits. A flow that queries or updates records inside a loop passes a one-record test, then fails during a data load. Use collections, act on many records in one element, and test with a realistic batch before activation.
Plan the Failure Before It Happens
Without a fault path, a failing flow stops with a generic message and few details. A good fault path tells the user what happened, logs the error, and alerts the right person. Decide on purpose whether the original save should still finish.
Split by Purpose, Reuse With Subflows
Split a flow when it mixes unrelated jobs, uses different entry conditions, or becomes hard to read and test. Control sequence with trigger order, move repeated logic into subflows, and keep one owner and one naming pattern for every object.
Why Flow Best Practices Start With the Transaction
Every record save runs inside a transaction, and each transaction receives a fixed budget of queries, updates, and processing time. Salesforce’s Apex developer guide lists the synchronous limits: 100 SOQL queries, 150 DML statements, 50,000 records retrieved, 10,000 records processed by DML, and 10 seconds of CPU time. Asynchronous work receives higher ceilings for some limits, such as 200 queries and 60 seconds of CPU time. You can review the full list in the Apex governor limits reference.That page describes code, not flows. However, record-triggered flows run as steps inside the same save, so plan as if they draw from the same budget. Confirm the details for your release before you rely on any figure, because Salesforce can change limits between releases and some apply differently to asynchronous work. If you are still choosing between tools, our guide to Agentforce, Flow, and Apex compares where each one fits.
A data load can start many interviews of the same record-triggered flow in one transaction. Salesforce can group database operations when those interviews reach the same bulkifiable element, reducing the number of queries and statements. However, this does not eliminate repeated database work inside an individual interview’s loop. Keep Get Records and record-changing elements outside loops, use collections where appropriate, and test with realistic batches and different decision paths. All automation in the transaction still shares its limits.
Bulkification: Building Flows That Handle 200 Records at Once
Bulkification means building a flow so it handles groups of records efficiently. Salesforce groups some flow operations for you when several records trigger the same flow in one transaction. That help does not protect a flow that performs an expensive step inside a loop, so the builder still carries part of the work.
What Bulkification Means in Practice
A bulkified flow avoids database operations that repeat unnecessarily for each item in a loop. It retrieves the required data, prepares changes in memory, and saves collections through as few database operations as the process reasonably needs. Efficient batching reduces query and statement counts, but the total number of records retrieved or changed still matters. Splitting a flow or calling a subflow does not, by itself, create a new transaction or reset its governor limits.
Query Once and Update Once
Use one Get Records element to pull the records you need into a collection. Salesforce’s Trailhead module on multirecord elements describes storing all matching records in one collection variable, with their fields and IDs. After changing values in memory, update the whole collection in one Update Records element. The same module covers Update Related Records, where one element updates every related record that matches your filter. The multirecord Trailhead module shows both approaches. Collections also make flows easier to read, because one retrieval element replaces a scattered series of lookups.
Filter Before You Touch Records
Narrow the records before the flow reads or changes them. The same Trailhead module filters an account’s cases so only open ones are updated, and it warns that updating a large set can slow a flow or exceed governor limits. Store only the fields you need, retrieve only the records that match, and use entry conditions so the flow does not start when it has no work to do. A smaller set of records means fewer loop passes, lower CPU use, and a shorter debug log when something goes wrong. It also reduces the chance that an unrelated record blocks the whole transaction.
Keep Database Operations Outside Loops
Use loops to evaluate records and prepare changes in memory. Keep Get Records, Create Records, Update Records, and Delete Records elements outside the loop so database operations do not repeat for every item. For example, when creating follow-up tasks for several opportunities, build each task inside the loop using Assignment elements and add it to a record collection. After the loop finishes, use one Create Records element to save the collection. This pattern reduces repeated database work and helps the flow stay within transaction limits as record volumes increase.
Keeping Queries and Updates Out of Loops
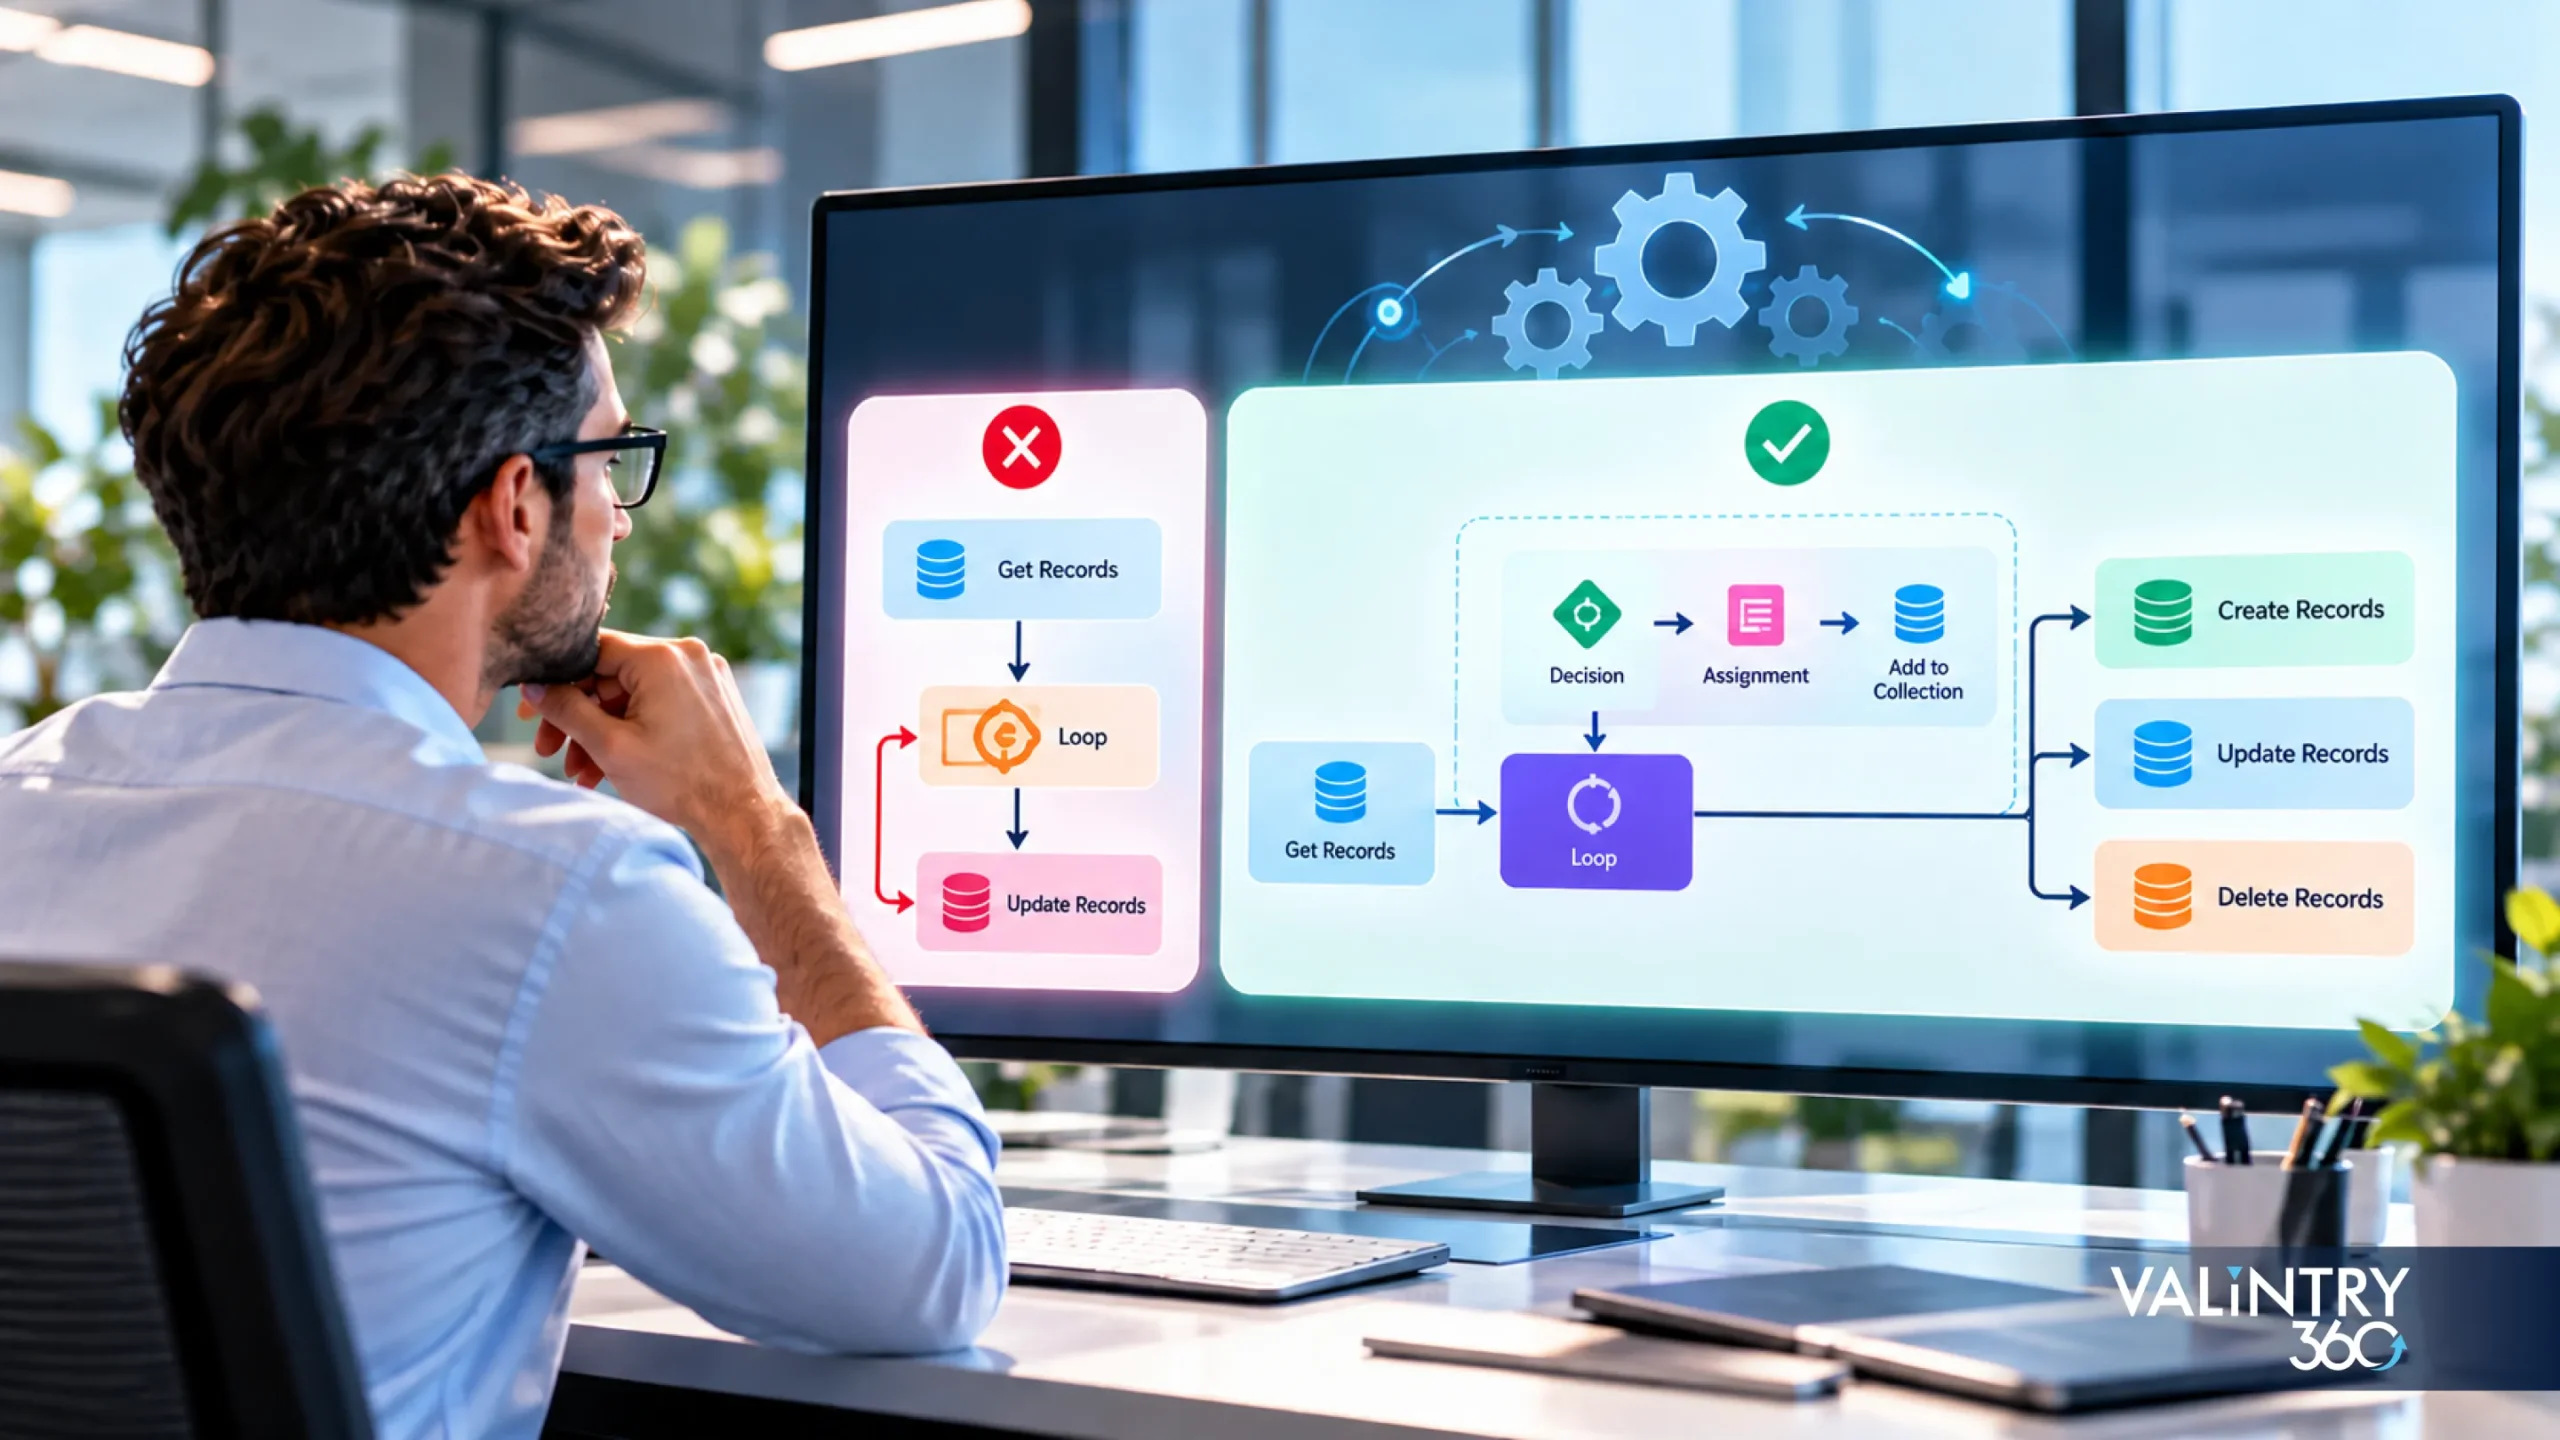
- Retrieve records before looping. Place Get Records outside the loop to avoid repeating queries for each record.
- Store records in a collection. Gather matching records together so the loop can process the retrieved data.
- Evaluate records within the loop. Use Decision elements to identify which records need changes before preparing updates.
- Prepare changes using assignments. Use Assignment elements to modify field values in memory during each loop iteration.
- Collect records for database operations. Add prepared records to a collection instead of saving them individually during processing.
- Create records after the loop. Use one Create Records element to save the new records in your collection.
- Update records after the loop. Use one Update Records element to save the modified records in your collection.
- Delete records after the loop. Use one Delete Records element to remove the selected records in your collection.
Entry Conditions and Before-Save Flows
Set entry conditions so a record-triggered flow starts only when it has useful work to do. For a one-time action, such as creating a task when an Opportunity enters a qualifying stage, configure the flow to run when the record changes to meet those conditions. When the process depends on a particular field changing, compare its current value with its previous value. Test an unrelated field update as well, so routine edits do not repeat the action.
Use a before-save flow when the task is to update fields on the record that triggered it. Assign the new field values directly to that record so the changes become part of the original save without a separate update operation. Use an after-save flow when the process needs to create related records, update another record, send an email, or perform another supported action. Choose the flow type according to the records and actions involved, then keep its entry conditions focused on that purpose.
Fault Paths: Deciding What Happens When a Flow Fails
Flows can fail because a required value is missing, a validation rule blocks a change, or a record is locked. A fault path can handle many element errors, allowing the flow to provide a useful message, record the failure, or notify an administrator. An unhandled fault stops execution, and the message shown depends on the flow type. Governor-limit failures are different: if the transaction exceeds a limit, Salesforce rolls it back even when the failing element has a fault path. Prevent those failures through efficient design and bulk testing.
A fault path is a secondary path from an element that runs only when that element fails. Salesforce says Get Records, Create Records, Update Records, Delete Records, and Action elements can each have one, as the fault paths module explains. Treat each one as a design decision rather than an afterthought. For every data element and action, ask what could fail, who needs to know, whether the original save should still go through, and what the user should see.
Should the Original Save Still Finish?
Decide whether a failed automation step should block the triggering record save. Handling a recoverable error through a fault path can allow the save to continue, which may suit a nonessential notification. If completing the automation is required for valid business data, use a Custom Error element in a supported before-save or after-save path to display a clear message and roll back the triggering change. Test both outcomes in a sandbox and confirm which records remain saved. A fault path cannot preserve a transaction that exceeds a governor limit.
What to Put Inside a Fault Path
Choose fault-path steps that suit the flow type and the business impact of the failure:
- Explain the failure clearly. In a screen flow, display a helpful error screen. In a supported record-triggered path, use Custom Error when the save must be rejected. Keep technical details for administrators.
- Record useful diagnostic details. Capture the flow name, record ID, error message, and time. Remember that a log record created in the same transaction can disappear if that transaction rolls back.
- Notify the responsible team. Review the error-email recipients in Process Automation Settings. Select the last modifying user or Apex Exception Email Recipients, and add a custom notification where the design requires one.
- Reuse compatible handling logic. Where subflows are supported, call a focused autolaunched handler with documented inputs. Test its behavior in each calling flow, including what happens if logging or notification fails.
If a flow regularly lands in its fault path, treat that as a defect to fix. Review the error log weekly at first, then monthly.Prevention beats handling. Salesforce’s example fixes a required field error by making the field required on the screen, so the fault never occurs. For predictable problems in screen flows, validate input before the data element runs, and show a clear message that tells the user how to correct it.
When to Split a Flow and When to Keep One
An older rule said to build one record-triggered flow per object and type. It came from Apex trigger habits, where one trigger per object keeps order under control. Salesforce now provides Flow Trigger Explorer and a Trigger Order value, so several flows on one object can run in a known sequence. That removes the strongest argument for putting everything in one flow.
Use the table below to decide whether to split, keep together, extract a subflow, or set the order. Each row describes a common situation, the approach that usually fits, and the action to take next, so you can check a flow against it in a few minutes.
Situation | Best Approach | Recommended Action |
|---|---|---|
The flow does unrelated jobs | Split | Create one flow for each job, each with its own entry condition and clear name. |
Parts run on different triggers, such as create and stage change | Split | Separate them so each flow skips the saves it does not need. |
Field updates and other actions share one flow | Split | Build a before-save flow for field updates and an after-save flow for the rest. |
Different teams own different parts | Split | Give each team its own flow and record the owner in the description. |
One process shares data and runs steps in a fixed order | Keep together | Keep one flow with labeled branches so the sequence stays easy to read. |
A split would repeat the same queries | Keep together | Query once and branch afterward to avoid spending extra limits. |
The same logic appears in several flows | Extract a subflow | Build a small subflow with documented inputs and outputs. |
Several flows change the same field | Set the order | Assign Trigger Order values in Flow Trigger Explorer and record the sequence. |
Before-save and after-save logic always belongs in separate flows, because they run at different points in the save. Beyond that, a sensible default is one before-save flow and one after-save flow for each object and purpose, with clear entry conditions, then further splits as the logic grows.
Do not split only to make the canvas look tidy. Twelve tiny flows, each with its own queries, can cost more than one organized flow.
A Worked Example: Splitting an Opportunity Flow
Consider an admin team that inherited one after-save flow on Opportunity. It emails finance when a deal reaches Closed Won, creates a renewal task on a renewal stage, and updates a related account field whenever the amount changes. This is an example, not data from a real org. The flow has grown to dozens of elements, and every small edit risks breaking another job. Nobody wants to touch it before quarter end, so defects wait. Splitting it gives each job a clear owner, a clear trigger, and a test plan small enough to finish.
Step 1: Review the Combined Flow
List every job the flow performs, the condition that starts each one, and the records it touches. In this example, the three jobs use three different triggers. Note which jobs only set fields on the Opportunity and which change other records, because that decides the flow type for each new flow. Ask which team relies on each job, so the right people can review the change.
Step 2: Separate the Jobs
Create three focused after-save flows: one to notify finance, one to create renewal tasks, and one to update the related Account. Each job in this example requires an after-save action. Give each flow entry conditions that reflect the relevant stage or field change, along with a clear name, purpose, and owner. If the original flow also contains simple updates to fields on the triggering Opportunity, move those updates into a separate before-save flow.
Step 3: Set the Order and Fault Paths
Open Flow Trigger Explorer and assign Trigger Order values with gaps between numbers. Add fault paths to every data element and action. Send errors to a shared inbox instead of the last person who edited the flow, so a failure in one job does not go unnoticed. Test each fault path by forcing an error in a sandbox.
Step 4: Test and Cut Over
In a sandbox, test the original flow and its replacements separately using equivalent starting data, then compare the resulting records and actions. Include a 200-record batch, mixed decision outcomes, repeated updates, and several Opportunities linked to the same Account. Plan a controlled cutover that prevents records from being processed while the old and replacement designs overlap or are both inactive. Retain the original configuration and a documented rollback procedure, then monitor for duplicate tasks, missing notifications, unexpected Account changes, and flow errors.
Controlling Order With Flow Trigger Explorer
Flow Trigger Explorer helps you review record-triggered flows for an object and trigger, including before-save flows, after-save flows, and associated asynchronous paths. For before-save and after-save flows, assign a Trigger Order value from 1 to 2,000 to control the sequence within the applicable group. That value cannot override Salesforce’s overall order of execution and has no direct effect on associated scheduled or asynchronous paths. When several flows change the same field, document their intended responsibilities and test the combined result rather than relying on order alone.
Follow these simple rules for every object:
- Leave gaps: Use numbers such as 10, 20, and 30 so you can insert a flow later.
- Prepare before acting: Run flows that prepare data before flows that depend on it.
- Document the sequence: Write the intended order in each flow’s description.
- Check before adding: Open the explorer before you add any new flow to an object.
The explorer has limits. It covers record-triggered flows only, and subflows called inside them do not appear. The order of execution reference shows where before-save flows, workflow rules, and after-save flows sit among triggers and validation rules. Work placed on the asynchronous path runs apart from the record’s save transaction, which suits slower work such as callouts, as long as it also has a fault path. If an object still carries older automation, read that reference before you reorder anything, because workflow rules and processes run at different steps.
Subflows and Reuse
- Build shared logic once. Use subflows for repeated tasks, such as fault handling, task creation, or common calculations, to reduce duplication and keep behavior consistent.
- Choose a supported flow type. Use subflows in after-save flows and screen flows where appropriate. Before-save record-triggered flows do not support the Subflow element.
- Keep screen interactions compatible. Call subflows that contain screens only from other screen flows, so the calling flow can support the required user interaction.
- Document callers and dependencies. Record which flows call each subflow, since its list view does not show callers and Trigger Explorer does not display nested subflows.
- Define clear inputs and outputs. Pass in the data the subflow needs and return useful results, avoiding extra queries for information the caller already holds.
- Keep each subflow focused. Give it one clear responsibility, such as creating a task or returning a calculation, so administrators can understand and test it easily.
- Manage shared changes carefully. Use stable names and document input and output variables. Review dependent flows when changing the subflow’s behavior or interface, and test affected callers.
- Check existing logic before building. Reuse a suitable subflow when one exists, and extract repeated logic when appropriate to prevent near-duplicates from accumulating across the org.
Testing Flows for Bulk and for Failure
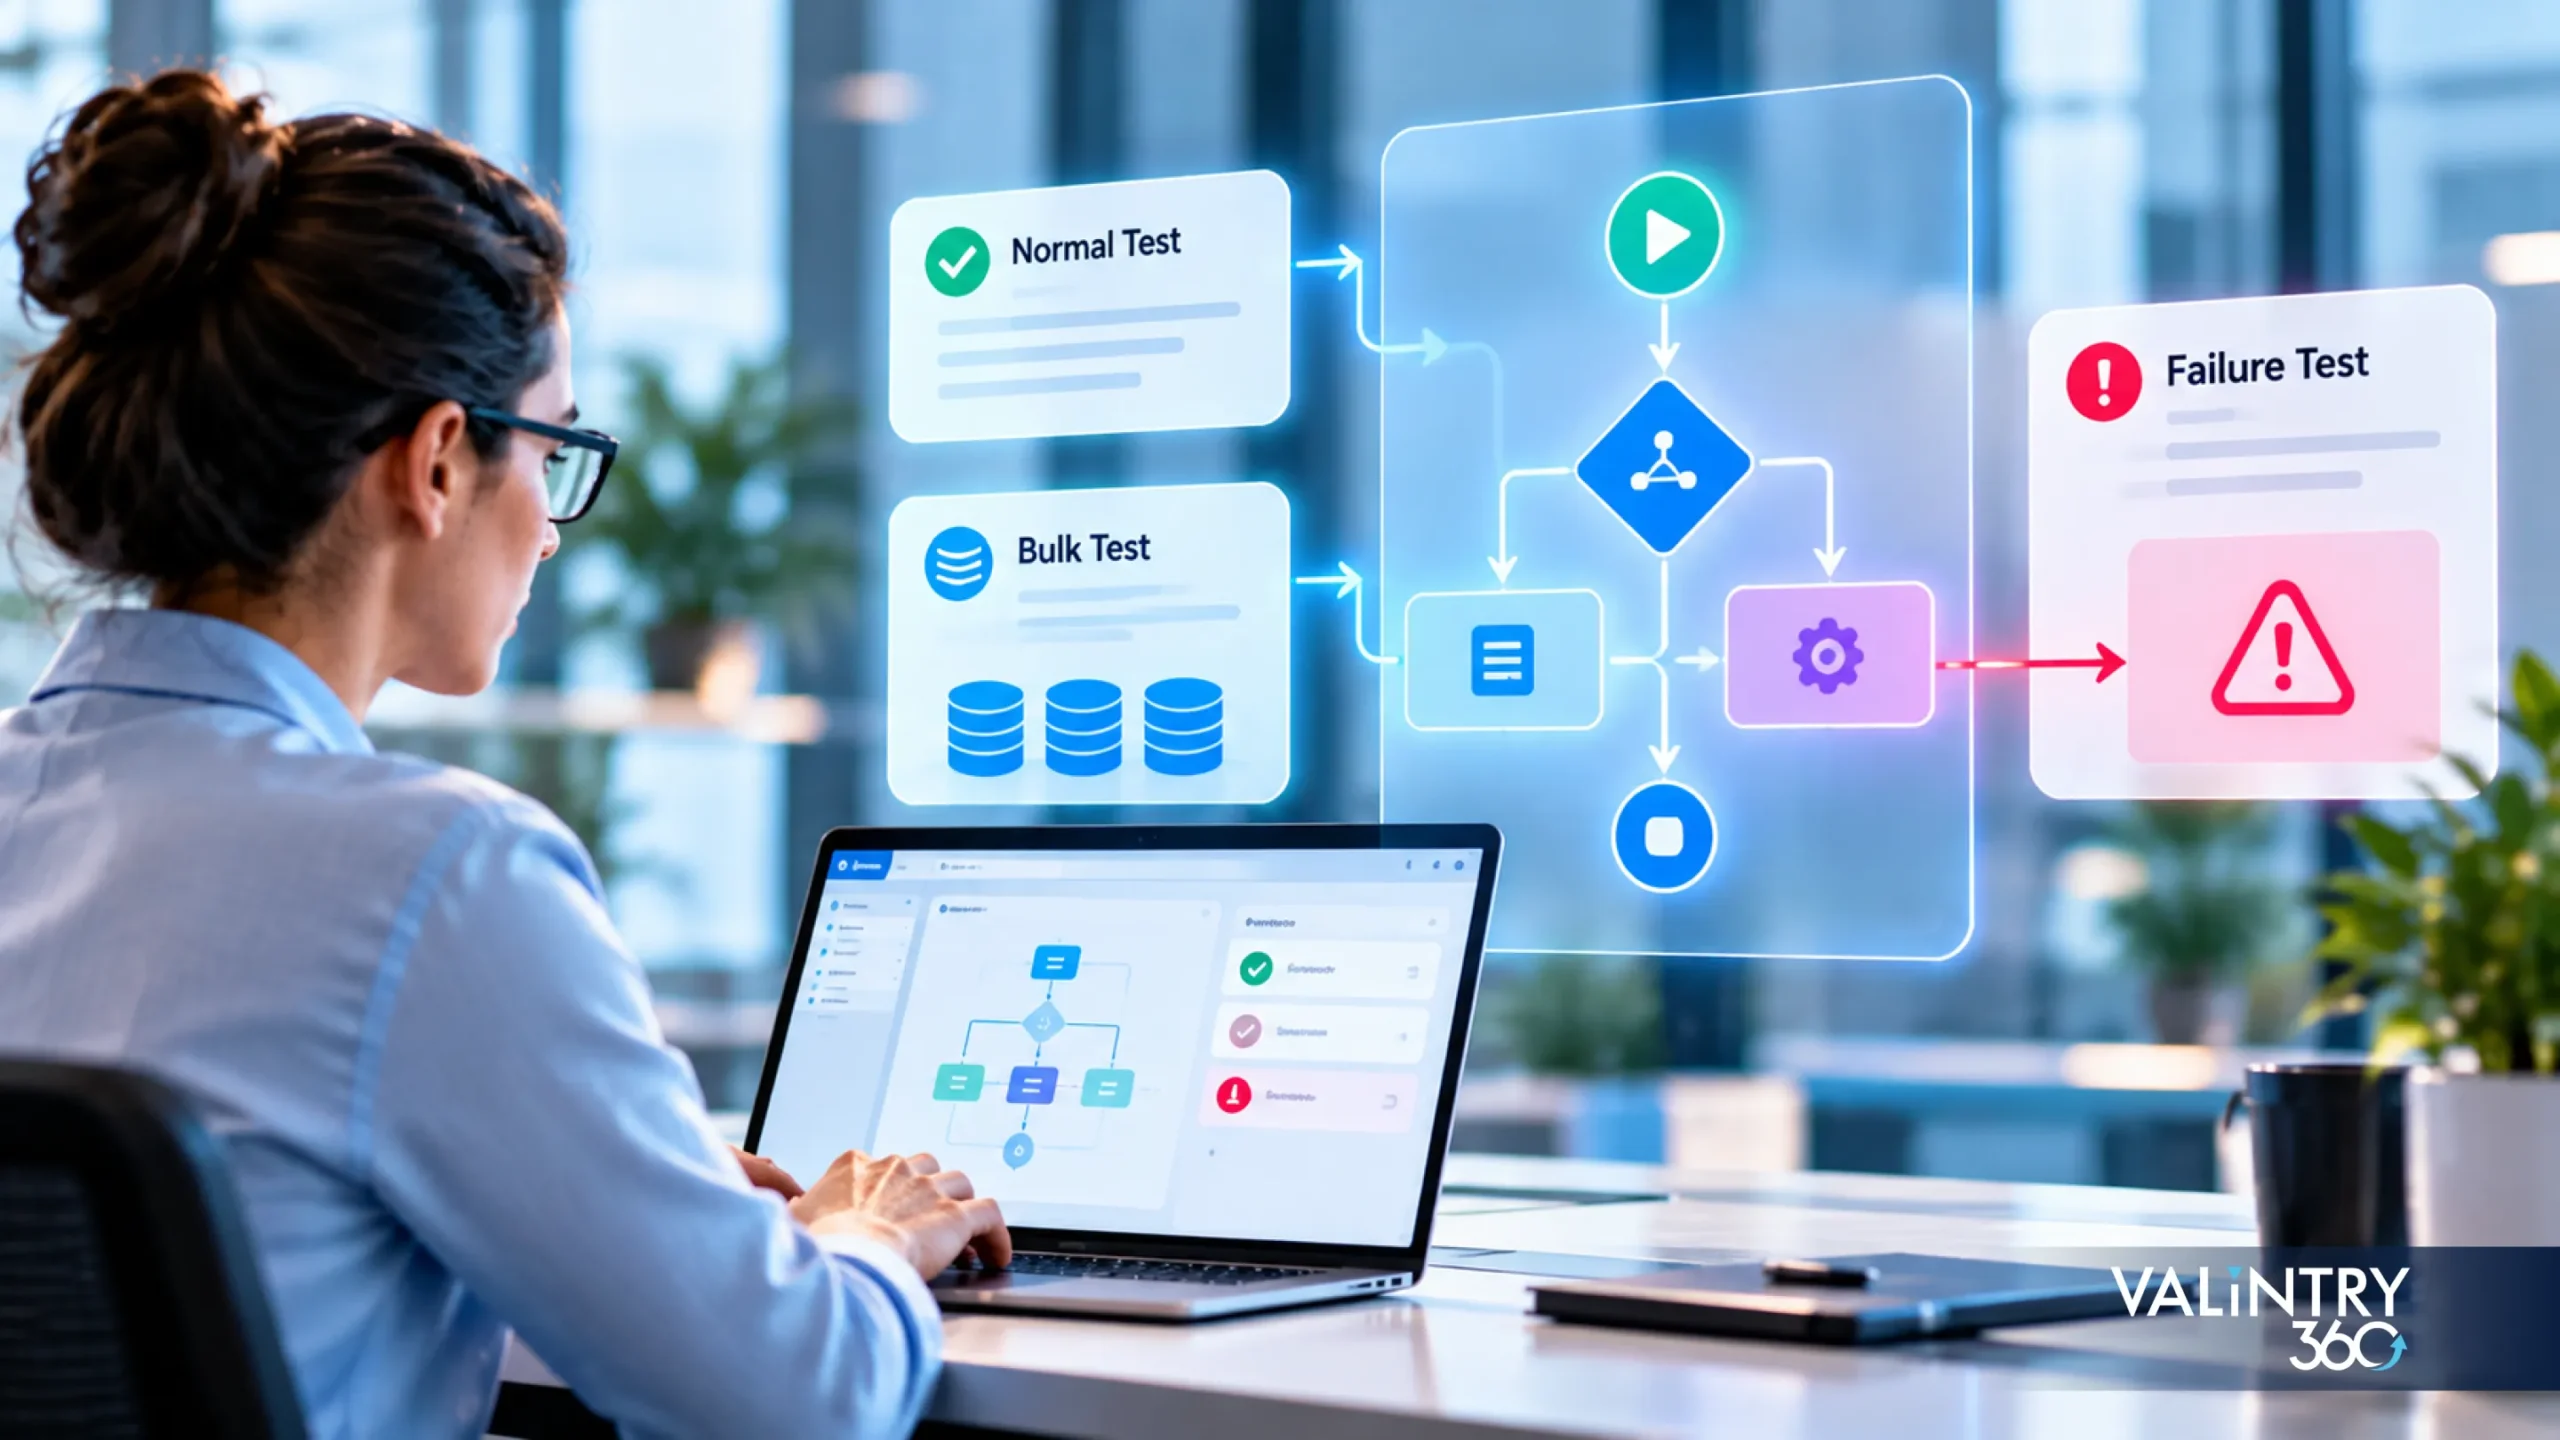
Test normal behavior, bulk processing, and failure handling before activation. Normal-use tests should verify the expected field changes, related records, and actions. Bulk tests should include a 200-record batch, records taking different branches, and records sharing the same parent. For failure tests, deliberately trigger a controlled error, such as a validation-rule failure or a missing required value. Choose the failure according to the flow’s execution context: removing a user permission may not affect a flow running in system context. Confirm the resulting message, notification, log, and save or rollback behavior.
Use Flow Tests for Logic
Use automated flow tests to check expected logic, including decision outcomes, triggering-record field values, and whether an action was visited. Salesforce’s flow tests module demonstrates tests for record creation and updates. Define assertions from the business requirement so the tests check the intended result. The Salesforce Admins article on testing record-triggered flows provides additional examples, but its 2022 feature limitations should not be treated as current specifications. Keep separate bulk and integration tests to verify behavior beyond the individual test scenario.
Keep a Standard Test Set
Flow tests do not replace a volume test, so keep your own set of test records for each object: a normal record, one with blank optional fields, one owned by an inactive user, and one that already meets the entry condition. Reusing the same set makes results easy to compare after every change, and it gives a new administrator a ready starting point for regression checks. Never debug with live production data, and remember that tests only prove the cases you write. Add a new test whenever a defect reaches production. If you want help finding your riskiest flows first, our free Salesforce audit scores automation and returns a fix plan.
Naming, Documentation and Version Hygiene
Good habits turn a pile of flows into a system. They cost little, and they pay back every time someone opens the org. Our guide on preventing technical debt and security issues covers the wider practice.
Set these standards for every flow, and write them down where every administrator can find them:
- Naming: Use a pattern with object, trigger type, and purpose, such as Opportunity_AfterSave_Notify_Finance.
- Descriptions: State what the flow does, why it exists, who owns it, and which flows depend on it.
- Element labels: Rename every element so it describes the action, such as Get Open Cases for Account.
- Version control: Keep the active version and one recent rollback version, and remove the rest.
- Ownership: Assign one person to approve new automation on each object.
- Release process: Build and test in a sandbox, then deploy through your normal process so every change has a record.
Review active flows, error logs, and slow executions every quarter, and record each finding with an owner and a due date. If your team lacks the time, a managed arrangement can own that work, and our guide on hourly consultants versus managed services explains how to choose.
Where Flow Falls Short and Apex Fits
Flow is powerful, but some requirements call for Apex. Consider it when a job involves very large record volumes, complex logic that would require many nested elements, greater control over transaction handling and retries, or calculations that strain CPU time. Warning signs include repeated query, DML, or CPU limit errors after optimization; a canvas that administrators struggle to understand; testing that leaves important paths uncovered; and noticeable delays when users save records. These symptoms warrant a design review, though they do not automatically mean Apex is necessary. If several appear together, consider moving the demanding work to Apex or splitting the flow before adding more logic. Review automation on busy objects at least annually, and use Salesforce’s Architect decision guides to compare tools against your requirements.
Apex also carries deployment, testing, and maintenance responsibilities, so use it where those costs are justified. A mixed approach can work well: Flow coordinates the process while an Apex action handles a demanding calculation or specialized operation. Design that action to accept collections and process records efficiently so it supports bulk execution. When custom code is needed, you can hire a Salesforce developer for those components while your administrators maintain the surrounding process in Flow. For broader projects, our Salesforce implementation services cover setup, integration, and post-launch support, helping teams plan how declarative automation and custom development work together.
Conclusion
Good Flow work comes down to three habits: build for batches, plan for failure, and split by purpose. A collection instead of a loop, a fault path with a real message, and a clear rule for dividing flows prevent most of the trouble teams meet as automation grows. Testing and naming keep the result readable.
Start with the flow that touches your busiest object. Test it with a few hundred records, review its fault paths, and give it a clear name. Then apply the same checks to the next flow, and keep a short record of what you changed and why. Small, steady improvements beat a large cleanup that never starts, and your future administrators will thank you for the notes.
A Team of 100+ Salesforce Professionals Backed by Certified Experts
VALiNTRY360 brings together 100+ Salesforce professionals, backed by certified experts in administration, development, data, AI, consulting, and marketing automation. Our listed certifications include Platform Administrator II and Platform App Builder, which cover the admin and design skills good Flow work relies on.
We can review your existing flows, fix bulk and error handling problems, and build new automation the right way. Meet the team on our about us page, and connect with us to discuss your requirements.
FAQs
1. What does it mean to bulkify a flow?
Bulkifying a flow means building it to handle many records efficiently in one transaction. It queries once into a collection, changes records in memory, and updates the collection once after any loop, using about the same queries and updates for one record or 200.
2. Why do flows pass testing but fail during data loads?
Testing usually uses one record. A data load can trigger the same flow for hundreds of records in one transaction, so any query or update inside a loop multiplies and hits a limit. Test with a realistic batch in a sandbox.
3. What governor limits affect flows?
Salesforce’s Apex guide lists synchronous limits of 100 SOQL queries, 150 DML statements, 50,000 records retrieved, 10,000 records processed by DML, and 10 seconds of CPU time. Record-triggered flows run inside the save, so plan around those limits and verify current figures.
4. Can I put Get Records or Update Records inside a loop?
You can, but you should not. Each pass costs a query or an update, and the limits arrive quickly in a batch. Retrieve the records before the loop, change them in memory, add them to a collection, and update the collection once after the loop.
5. What is a fault path in Salesforce Flow?
A fault path is a secondary path from an element that runs only if that element fails. Get, Create, Update, and Delete Records and Action elements can have one. It lets you show a message, log the error, and alert someone.
6. What happens if a flow has no fault path?
Salesforce says the flow stops and the user sees a generic message that an unhandled fault occurred. A screen flow user has to start over, and Salesforce also sends an error email. Add fault paths so users and administrators receive useful details.
7. Should a failed flow stop the original record save?
It depends on the job. A fault path can let the triggering save finish even though your automation failed, which suits low-risk work such as a notification. If the flow sets data the business needs, you may want the save to fail.
8. Who receives the email when a flow fails?
By default, the error email typically goes to the person who last modified the flow, who may have left or may not own it. Add an email or notification action in the fault path that reaches a shared inbox or channel.
9. Should I build one flow per object?
No fixed rule requires it. Flow Trigger Explorer and Trigger Order let several record-triggered flows run in a set sequence, so you can split by purpose. A common default is one before-save and one after-save flow per object and purpose, then splitting further as logic grows.
10. When should I split a flow?
Split a flow when it does unrelated jobs, uses different entry conditions for different parts, is hard to read or test, or is owned by different teams. Keep it together when the logic is one process sharing data and a split would repeat the same queries.
11. How do I control the order of record-triggered flows?
Set a Trigger Order value in each flow’s properties and review the sequence in Flow Trigger Explorer, which groups flows by before-save, after-save, and asynchronous. Leave gaps between numbers, record the intended order in descriptions, and remember that subflows do not appear in the explorer.
12. When should I use a subflow?
Use a subflow for logic that repeats, such as a fault handler or a standard task creation. Change it once and every caller updates. Before-save record-triggered flows do not support subflows, and a subflow’s list view does not show its callers, so document who uses it.
13. How do I test a flow for bulk behavior?
Load a few hundred records into a sandbox with a data tool, then watch for limit errors and slow runs. Flow tests help with logic, but Salesforce’s own examples use one triggering record per test, so they do not replace a volume test.
14. What should every flow include?
Every flow should have a clear name, a description with owner and purpose, entry conditions, fault paths on data elements and actions, labeled elements, and a set of test records. Keep only needed versions, and assign one owner for approving changes on each object.
15. When is Apex better than Flow?
Apex fits very large volumes, complex logic that would need dozens of nested elements, fine control over transactions, and heavy calculation. Flow suits most everyday automation. A mix works well, with Flow orchestrating and an Apex action handling the heavy step.